The International Conference on Learning Representations (ICLR) is the premier gathering of professionals dedicated to the advancement of the branch of artificial intelligence called representation learning, but generally referred to as deep learning.
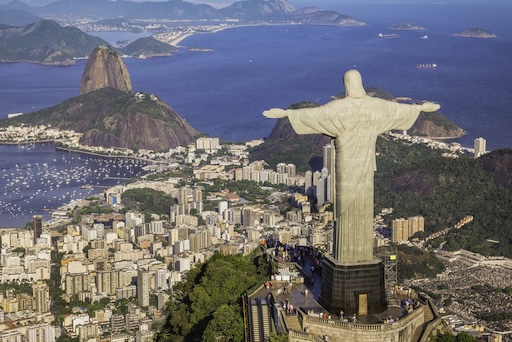
UCF IAI Faculty and their collaborators had 23 papers accepted into the (ICLR 2026) conference that will take place in Rio de Janeiro, Brazil from April 23-27, 2026.
The h5-index is the h-index for articles published in the last 5 complete years. According to Google Scholar Metrics, the International conference on Learning Representations (ICLR) is ranked 3rd in the h5-index rankings for the Engineering & Computer Science subcategory and 8thin the h5-index rankings for top venues.
You can access the IAI Publications Page to see accepted papers.
CRCV faculty contributed to these 7 papers.
Ashraf, Tajamul; Saqib, Amal; Gani, Hanan; AlMahri, Muhra; Li, Yuhao; Ahsan, Noor; Nawaz, Umair; Lahoud, Jean; Cholakkal, Hisham; Shah, Mubarak; Torr, Philip; Khan, Fahad; Anwer, Rao; Khan, Salman
Agent-X: Evaluating Deep Multimodal Reasoning in Vision-Centric Agentic Tasks Conference
Fourteenth International Conference on Learning Representations (ICLR), 2026., 2026.
@conference{Ashraf2026,

title = {Agent-X: Evaluating Deep Multimodal Reasoning in Vision-Centric Agentic Tasks},

author = {Tajamul Ashraf and Amal Saqib and Hanan Gani and Muhra AlMahri and Yuhao Li and Noor Ahsan and Umair Nawaz and Jean Lahoud and Hisham Cholakkal and Mubarak Shah and Philip Torr and Fahad Khan and Rao Anwer and Salman Khan},

url = {https://openreview.net/pdf?id=Vjruxvp1Xd},

year  = {2026},

date = {2026-01-26},

publisher = {Fourteenth International Conference on Learning Representations (ICLR), 2026.},

abstract = {Deep reasoning is fundamental for solving complex tasks, especially in vision-centric scenarios that demand sequential, multimodal understanding. However, existing benchmarks typically evaluate agents with fully synthetic, single-turn queries, limited visual modalities, and lack a framework to assess reasoning quality over multiple steps as required in real-world settings. To address this, we introduce Agent-X, a large-scale benchmark for evaluating vision-centric agents’ multistep and deep reasoning capabilities in real-world, multimodal settings. AgentX features 828 agentic tasks with authentic visual contexts, including images, multi-image comparisons, videos, and instructional text. These tasks span six major agentic environments: general visual reasoning, web browsing, security and surveillance, autonomous driving, sports, and math reasoning. Our benchmark requires agents to integrate tool use with explicit, stepwise decision-making in these diverse settings. In addition, we propose a fine-grained, step-level evaluation framework that assesses the correctness and logical coherence of each reasoning step and the effectiveness of tool usage throughout the task. Our results reveal that even the best-performing models, including GPT, Gemini, and Qwen families, struggle to solve multi-step vision tasks, achieving less than 50% full-chain success. These findings highlight key bottlenecks in current LMM reasoning and tool-use capabilities and identify future research directions in vision-centric agentic reasoning models},

keywords = {},

pubstate = {published},

tppubtype = {conference}

}
Singh, Utsav; Chakraborty, Souradip; Suttle, Wesley; Sadler, Brian; Asher, Derrik; Sahu, Anit Kumar; Shah, Mubarak; Namboodiri, Vinay Purushothaman; Bedi, Amrit
Direct Preference Optimization for Primitive-Enabled Hierarchical RL: A Bilevel Approach Conference
Fourteenth International Conference on Learning Representations (ICLR), 2026., 2026.
@conference{Singh2026,

title = { Direct Preference Optimization for Primitive-Enabled Hierarchical RL: A Bilevel Approach},

author = {Utsav Singh and Souradip Chakraborty and Wesley Suttle and Brian Sadler and Derrik Asher and Anit Kumar Sahu and Mubarak Shah and Vinay Purushothaman Namboodiri and Amrit Bedi

},

url = {https://arxiv.org/html/2411.00361v3},

year  = {2026},

date = {2026-01-26},

urldate = {2026-01-26},

publisher = {Fourteenth International Conference on Learning Representations (ICLR), 2026.},

abstract = {Hierarchical reinforcement learning (HRL) enables agents to solve complex, long-horizon tasks by decomposing them into manageable sub-tasks. However, HRL methods face two fundamental challenges: (i) non-stationarity caused by the evolving lower-level policy during training, which destabilizes higher-level learning, and (ii) the generation of infeasible subgoals that lower-level policies cannot achieve. To address these challenges, we introduce DIPPER, a novel HRL framework that formulates goal-conditioned HRL as a bi-level optimization problem and leverages direct preference optimization (DPO) to train the higher-level policy. By learning from preference comparisons over subgoal sequences rather than rewards that depend on the evolving lower-level policy, DIPPER mitigates the impact of non-stationarity on higher-level learning. To address infeasible subgoals, DIPPER incorporates lower-level value function regularization that encourages the higher-level policy to propose achievable subgoals. We introduce two novel metrics to quantitatively verify that DIPPER mitigates non-stationarity and infeasible subgoal generation issues in HRL. Empirical evaluation on challenging robotic navigation and manipulation benchmarks shows that DIPPER achieves upto 40% improvements over state-of-the-art baselines on challenging sparse-reward scenarios, highlighting the potential of preference-based learning for addressing longstanding HRL limitations.},

keywords = {},

pubstate = {published},

tppubtype = {conference}

}
Fioresi, Joseph; Dave, Ishan Rajendrakumar; Shah, Mubarak
Privacy Beyond Pixels: Latent Anonymization for Privacy-Preserving Video Understanding Conference
Fourteenth International Conference on Learning Representations (ICLR), 2026., 2026.
@conference{Fioresi2026b,

title = {Privacy Beyond Pixels: Latent Anonymization for Privacy-Preserving Video Understanding},

author = {Joseph Fioresi and Ishan Rajendrakumar Dave and Mubarak Shah},

url = {https://arxiv.org/abs/2511.08666},

year  = {2026},

date = {2026-01-26},

urldate = {2026-01-26},

publisher = {Fourteenth International Conference on Learning Representations (ICLR), 2026.},

abstract = {We introduce a novel formulation of visual privacy preservation for video foundation models that operates entirely in the latent space. While spatio-temporal features learned by foundation models have deepened general understanding of video content, sharing or storing these extracted visual features for downstream tasks inadvertently reveals sensitive personal information like skin color, gender, or clothing. Current privacy preservation methods focus on input-pixel level anonymization, which requires retraining the entire utility video model and results in task-specific anonymization, making them unsuitable for recent video foundational models. To address these challenges, we introduce a lightweight Anonymizing Adapter Module (AAM) that removes private information from video features while retaining general task utility. AAM can be applied in a plug and play fashion to frozen video encoders, minimizing the computational burden of finetuning and re-extracting features. Our framework employs three newly designed training objectives: (1) a clip-level self-supervised privacy objective to reduce mutual information between static clips, (2) a co-training objective to retain utility across seen tasks, and (3) a latent consistency loss for generalization on unseen tasks. Our extensive evaluations demonstrate a significant 35% reduction in privacy leakage while maintaining near-baseline utility performance across various downstream tasks: Action Recognition (Kinetics400, UCF101, HMDB51), Temporal Action Detection (THUMOS14), and Anomaly Detection (UCF-Crime). We also provide an....},

keywords = {},

pubstate = {published},

tppubtype = {conference}

}