

Distribution Shift
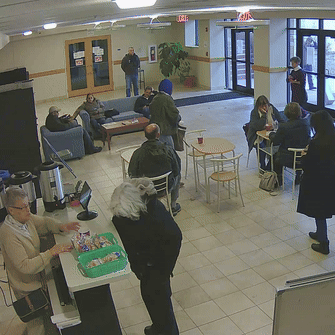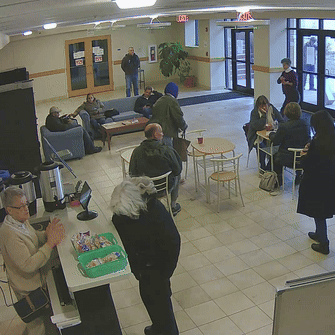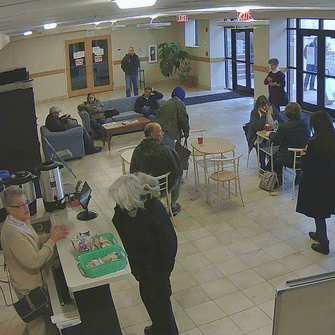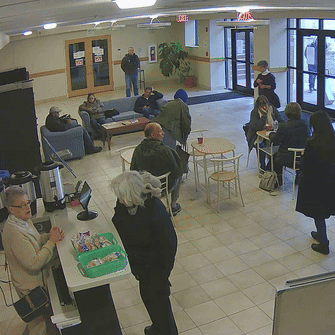
UCF101-DS [Distribution Shift]
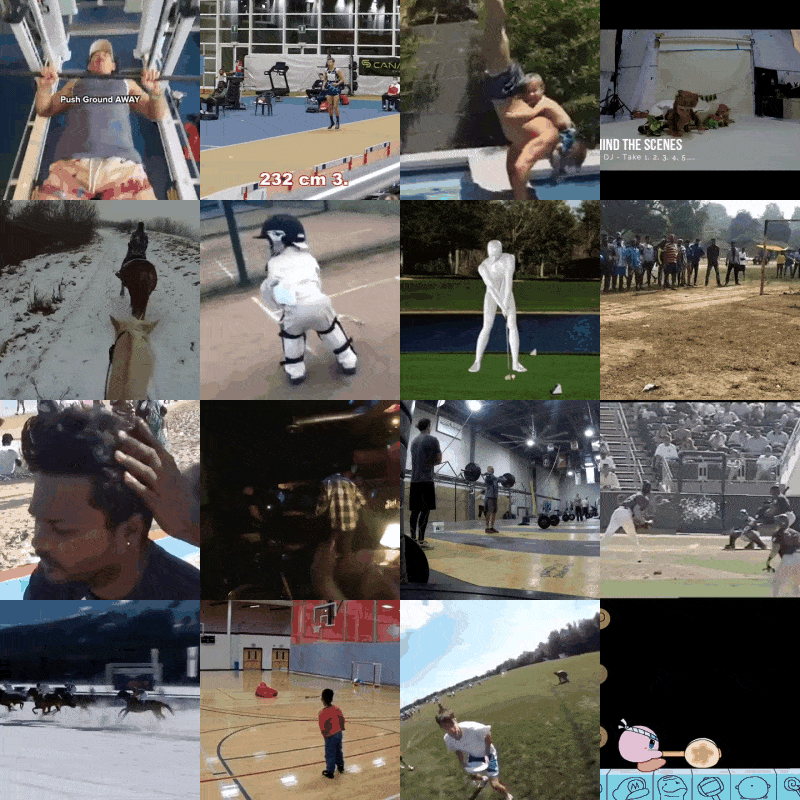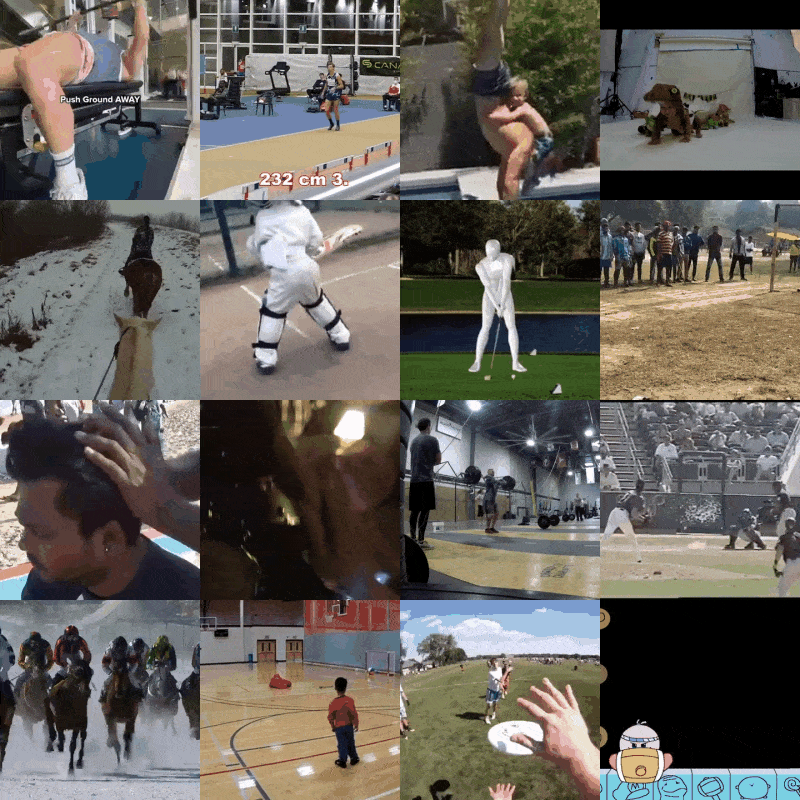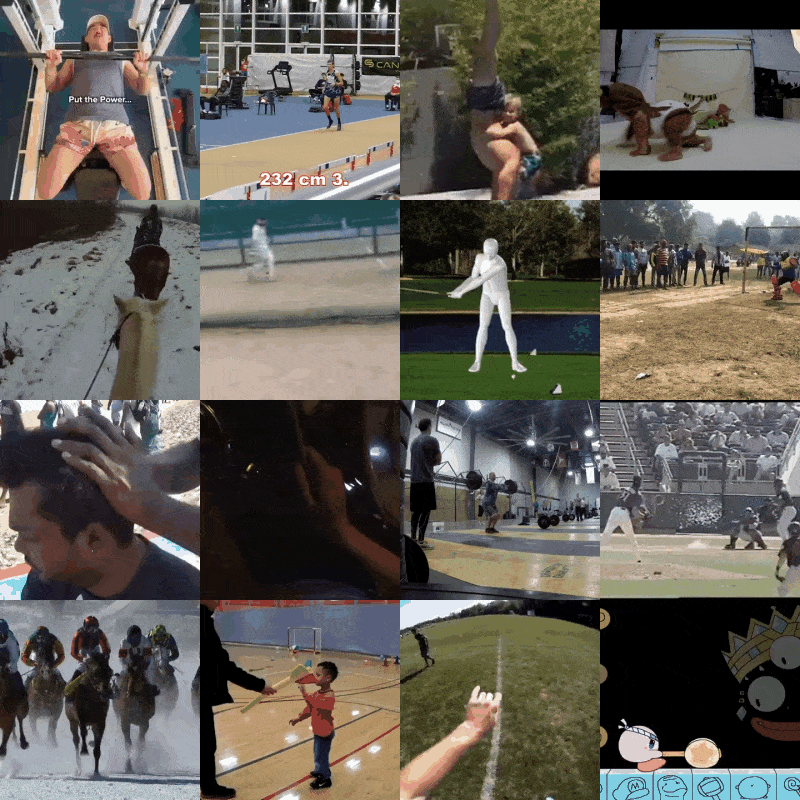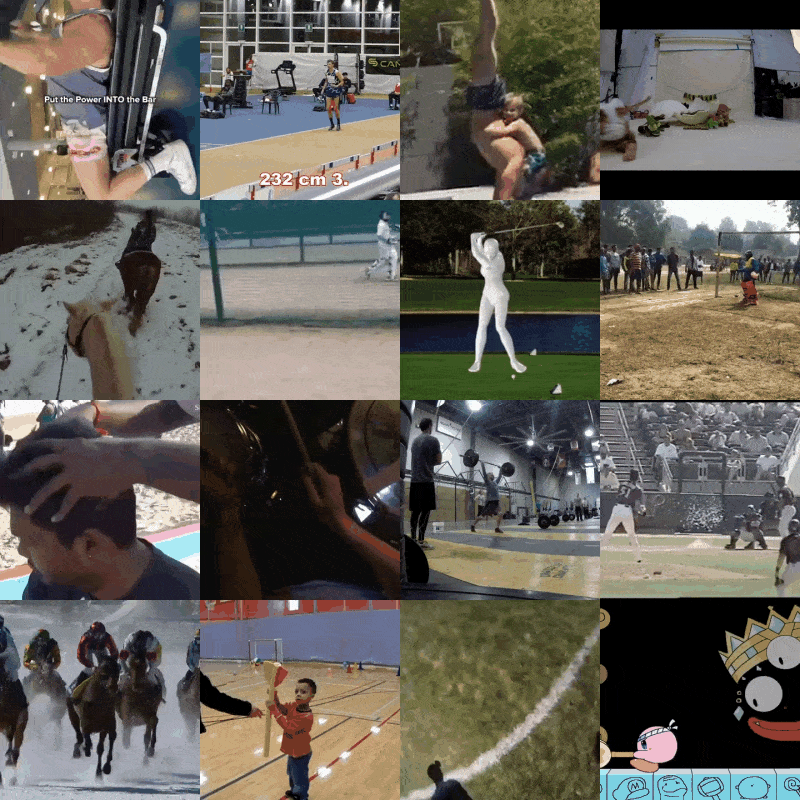
| No. of classes | No. of Videos | Distribution Shifts |
|---|---|---|
| 47 | 4708 | 63 |
A Large-scale Robustness Analysis of Video Action Recognition Models
Madeline Chantry, Naman Biyani, Prudvi Kamtam, Shruti Vyas, Hamid Palangi, Vibhav Vineet, and Yogesh Singh Rawat
CVPR 2023
Perturbation
HMDB51-P
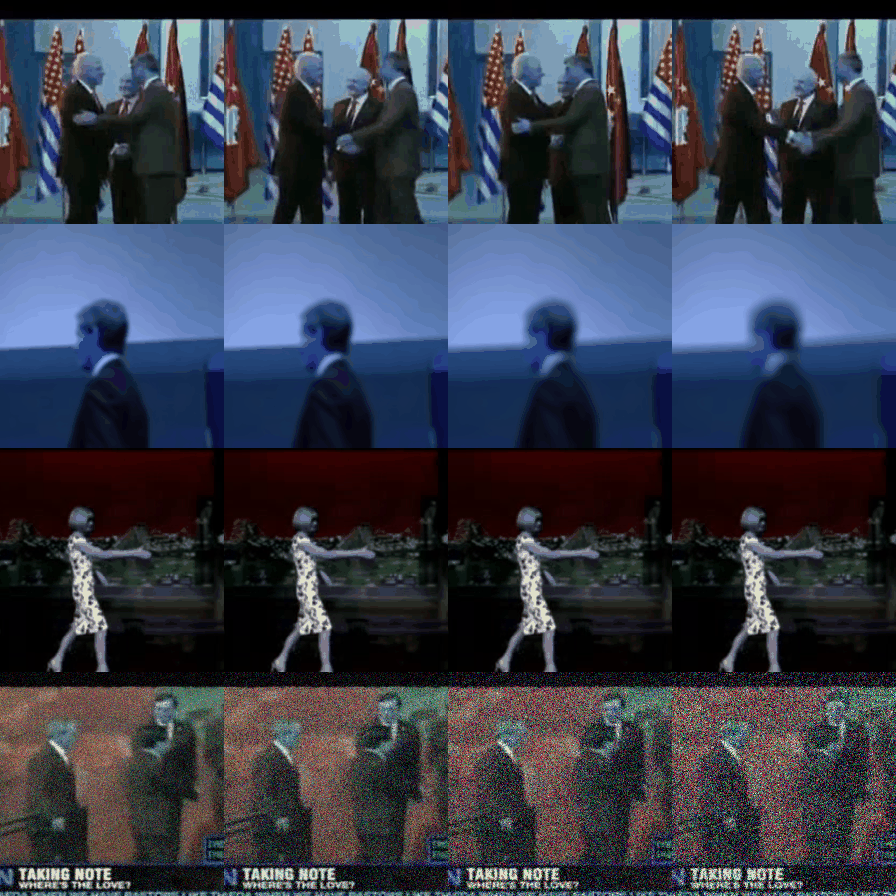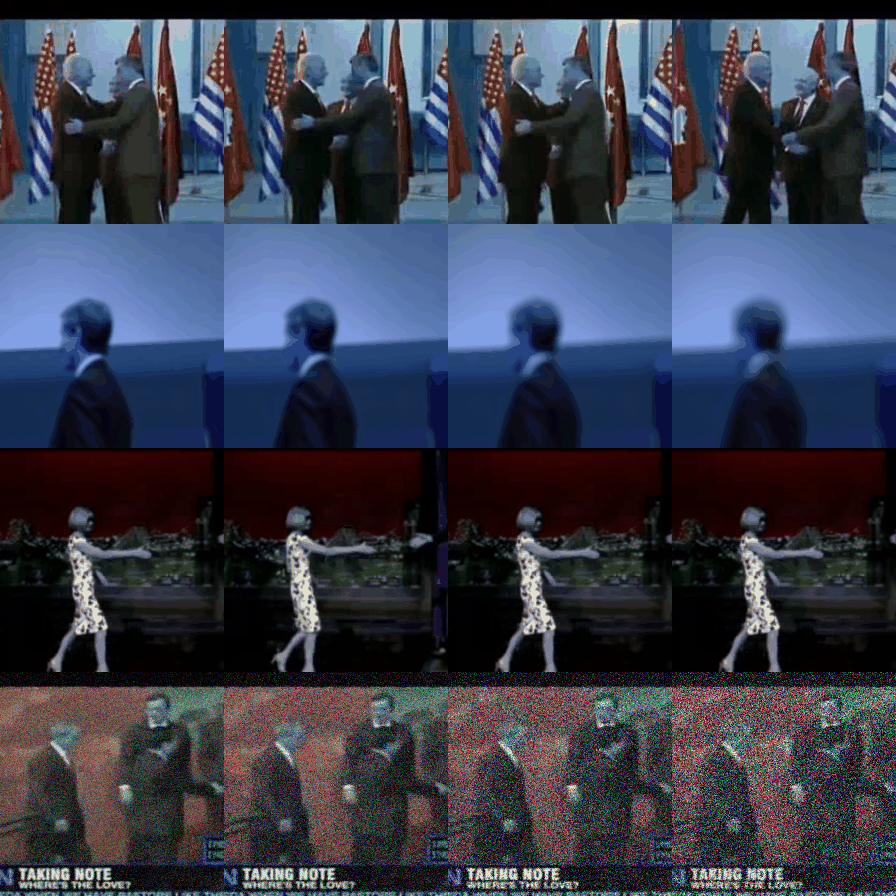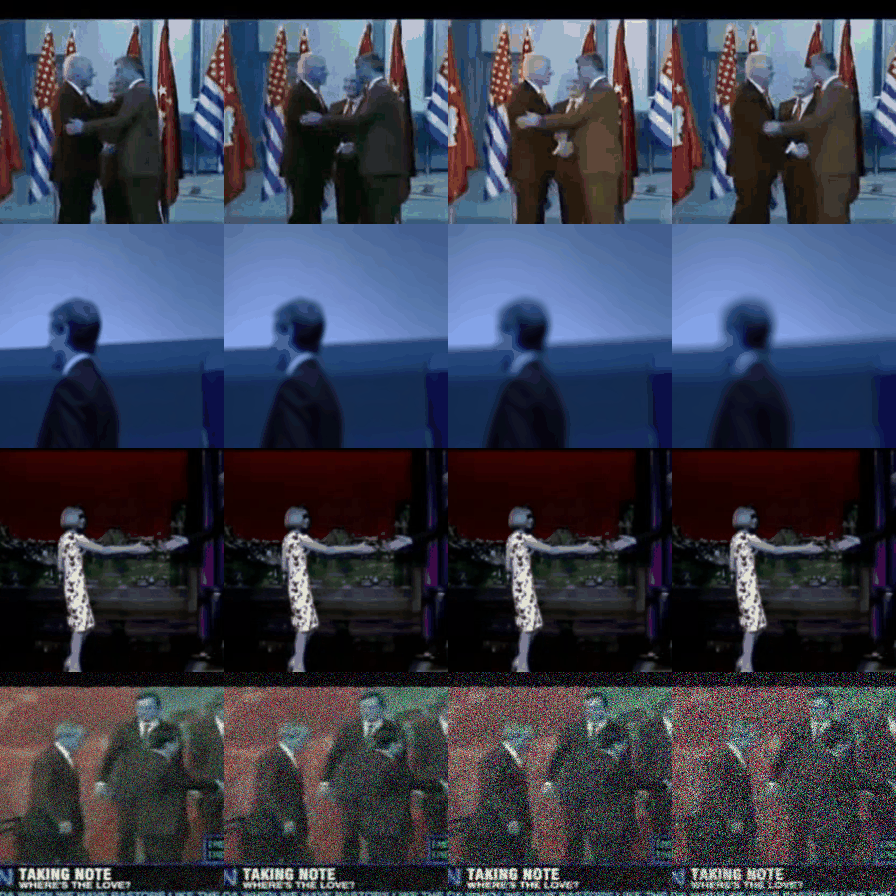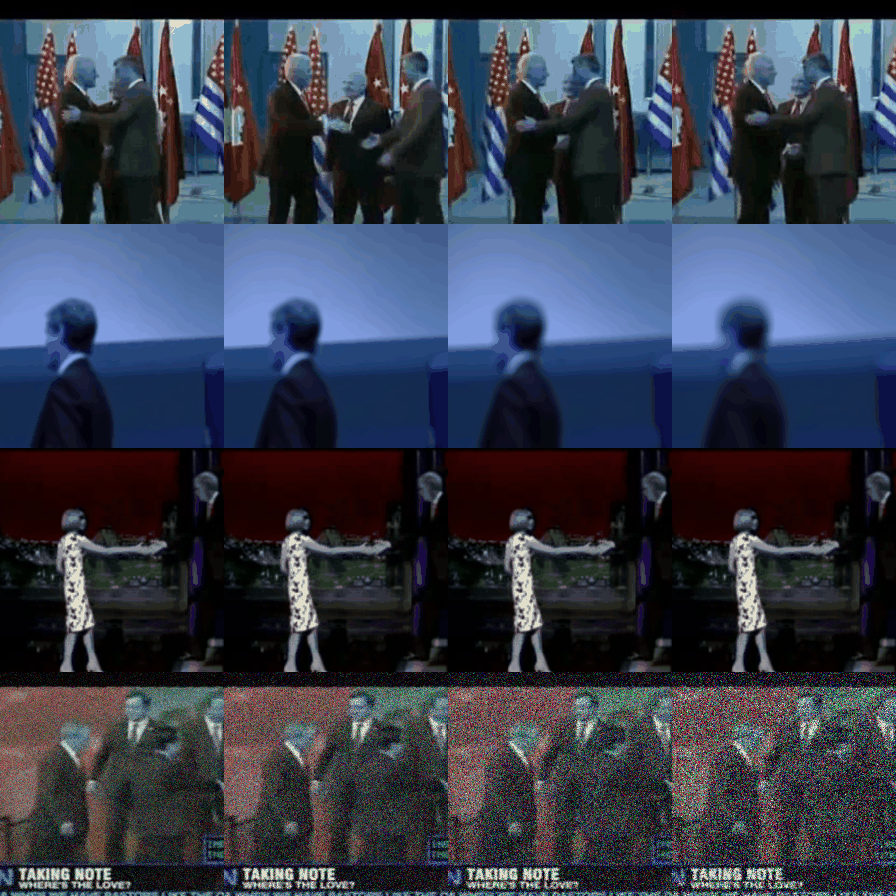
| No. of classes | No. of Videos | Perturbations |
|---|---|---|
| 51 | 137,610 | 90 |
A Large-scale Robustness Analysis of Video Action Recognition Models
Madeline Chantry, Naman Biyani, Prudvi Kamtam, Shruti Vyas, Hamid Palangi, Vibhav Vineet, and Yogesh Singh Rawat
CVPR 2023
UCF101-P
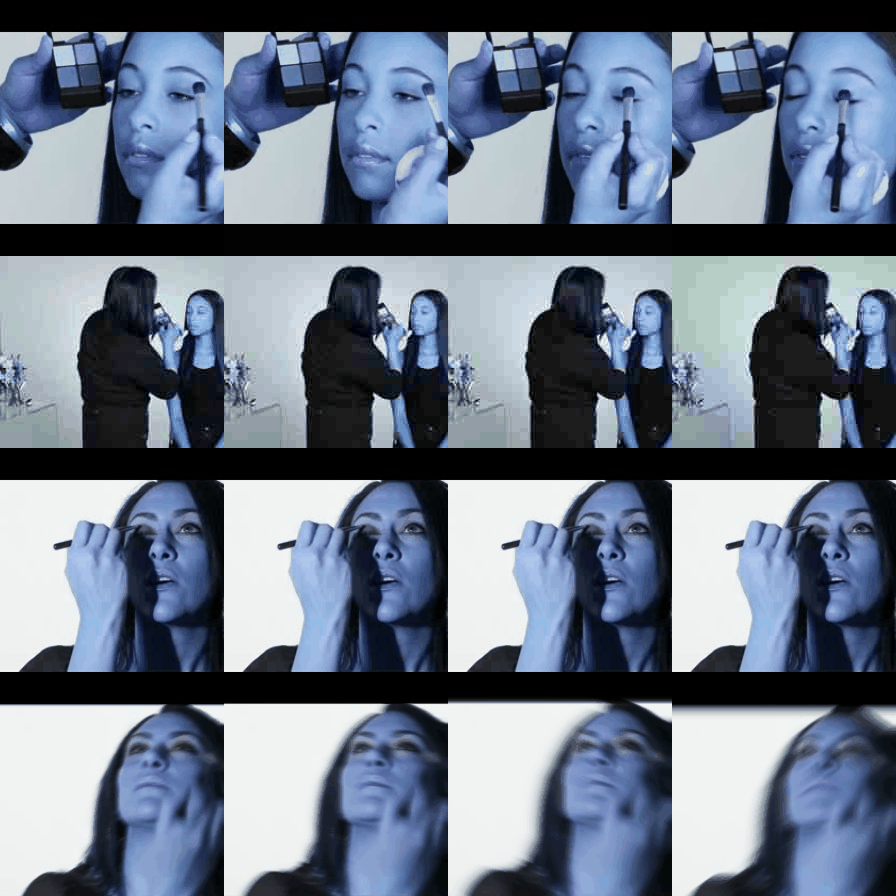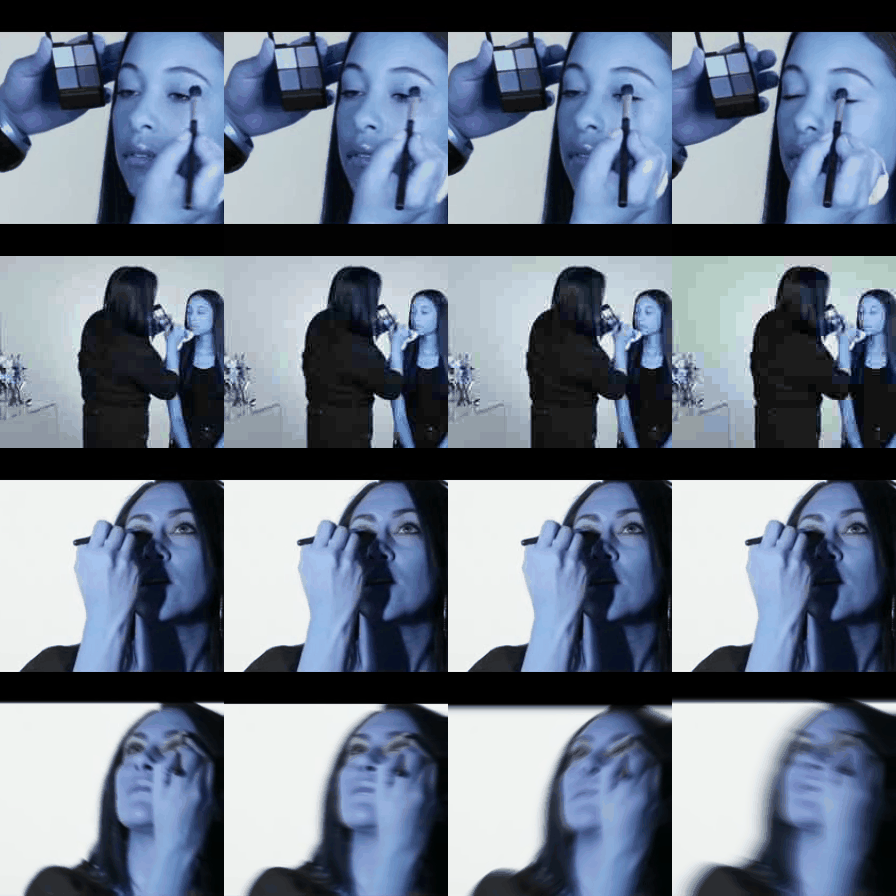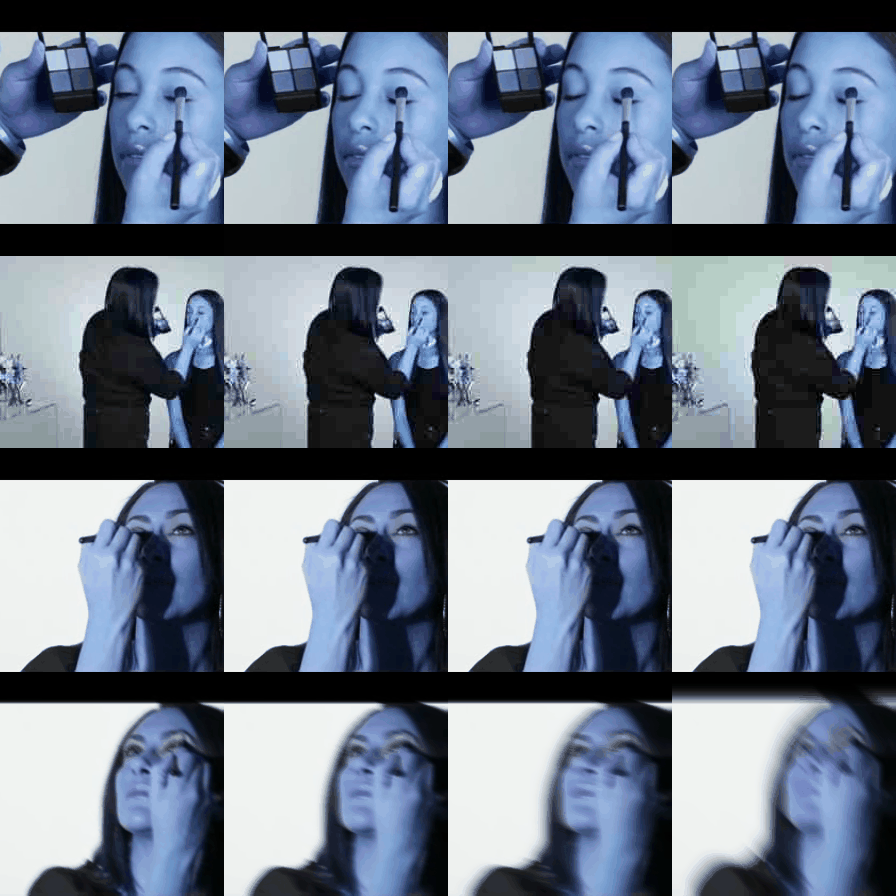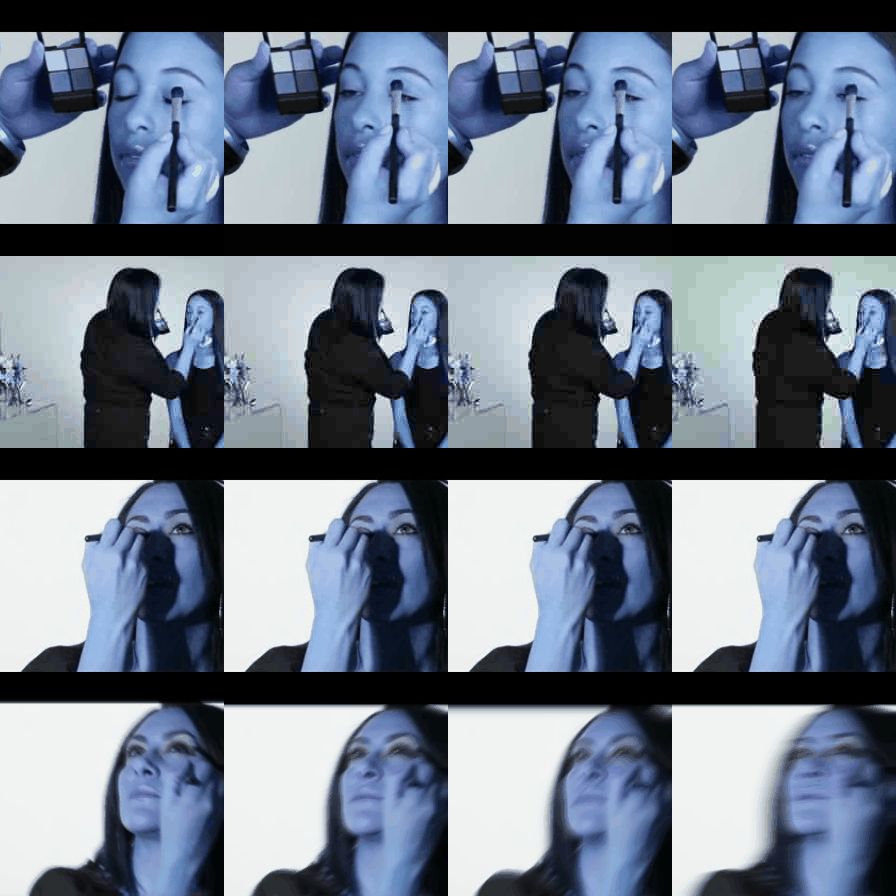
| No. of classes | No. of Videos | Perturbations |
|---|---|---|
| 101 | 340,380 | 90 |
A Large-scale Robustness Analysis of Video Action Recognition Models
Madeline Chantry, Naman Biyani, Prudvi Kamtam, Shruti Vyas, Hamid Palangi, Vibhav Vineet, and Yogesh Singh Rawat
CVPR 2023
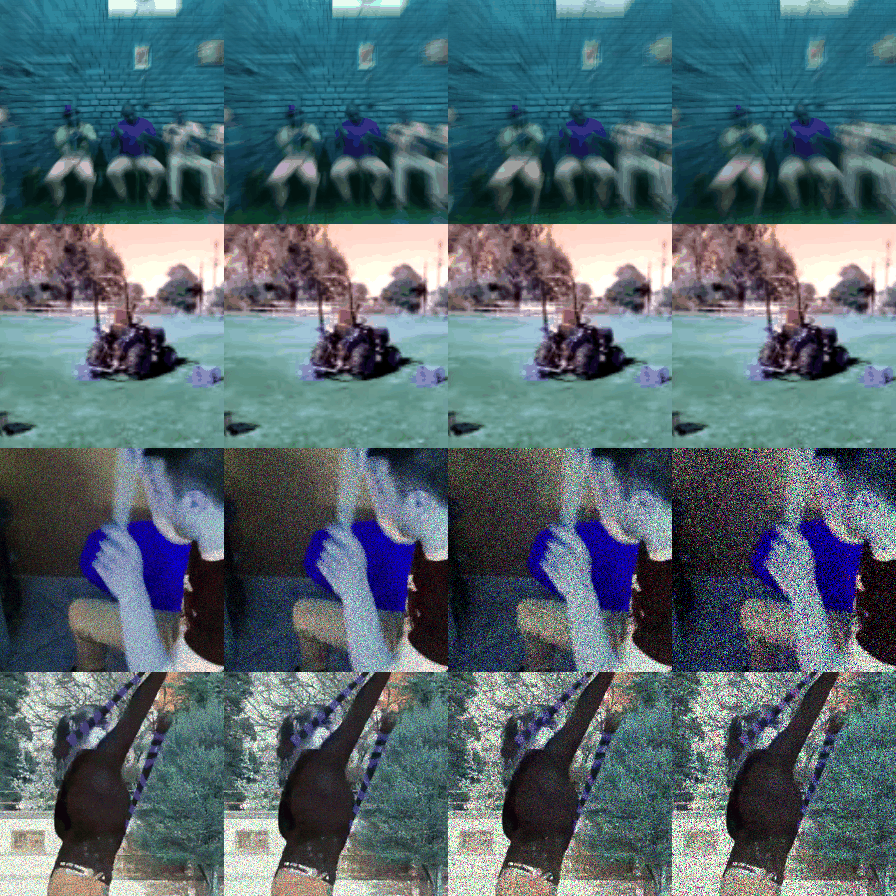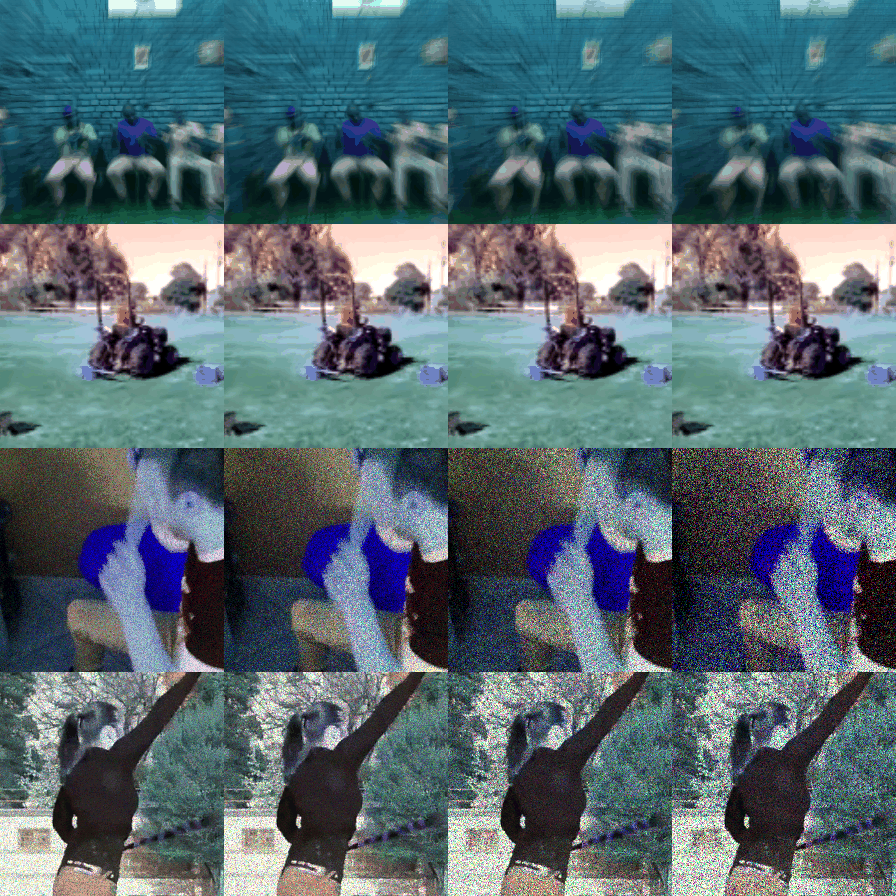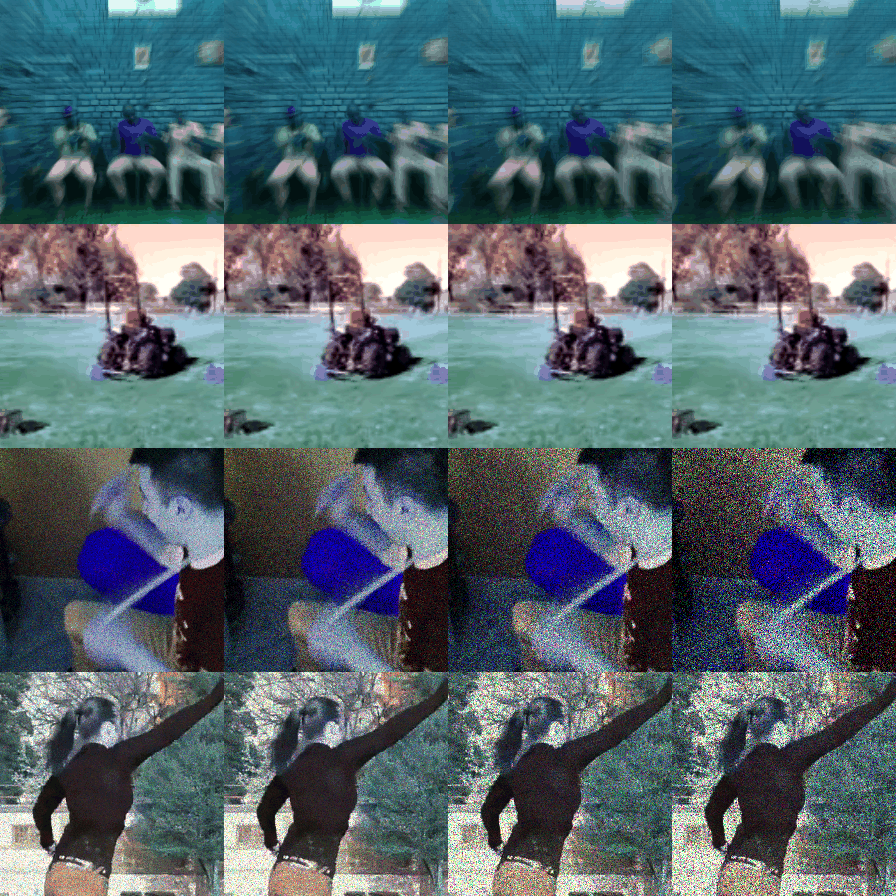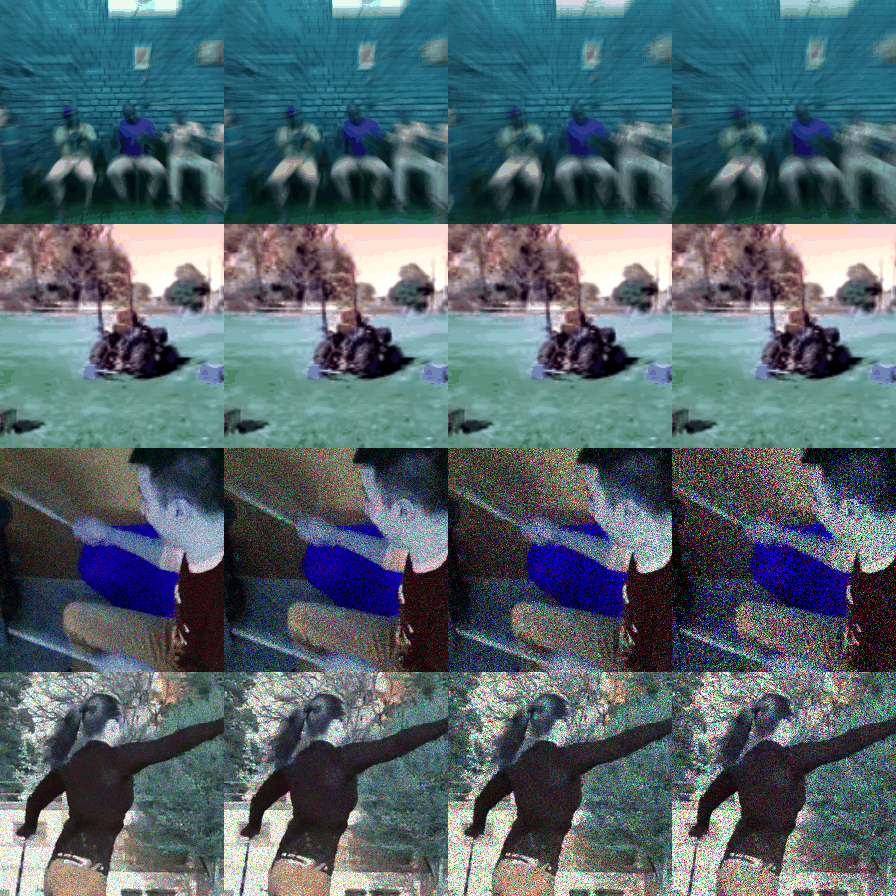
Kinetics400-P
| No. of classes | No. of Videos | Perturbations |
|---|---|---|
| 400 | 1,616,670 | 90 |
A Large-scale Robustness Analysis of Video Action Recognition Models
Madeline Chantry, Naman Biyani, Prudvi Kamtam, Shruti Vyas, Hamid Palangi, Vibhav Vineet, and Yogesh Singh Rawat
CVPR 2023
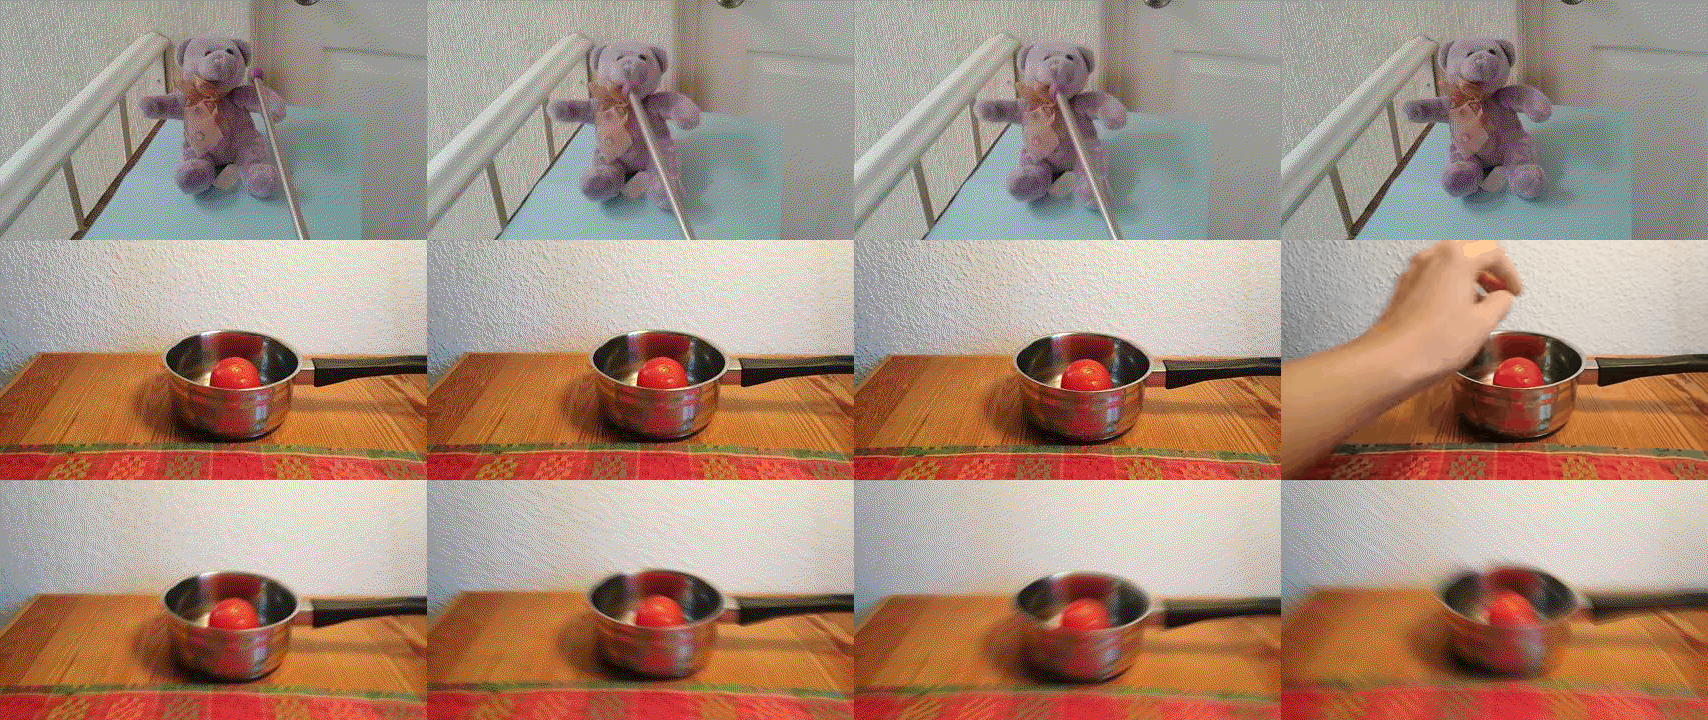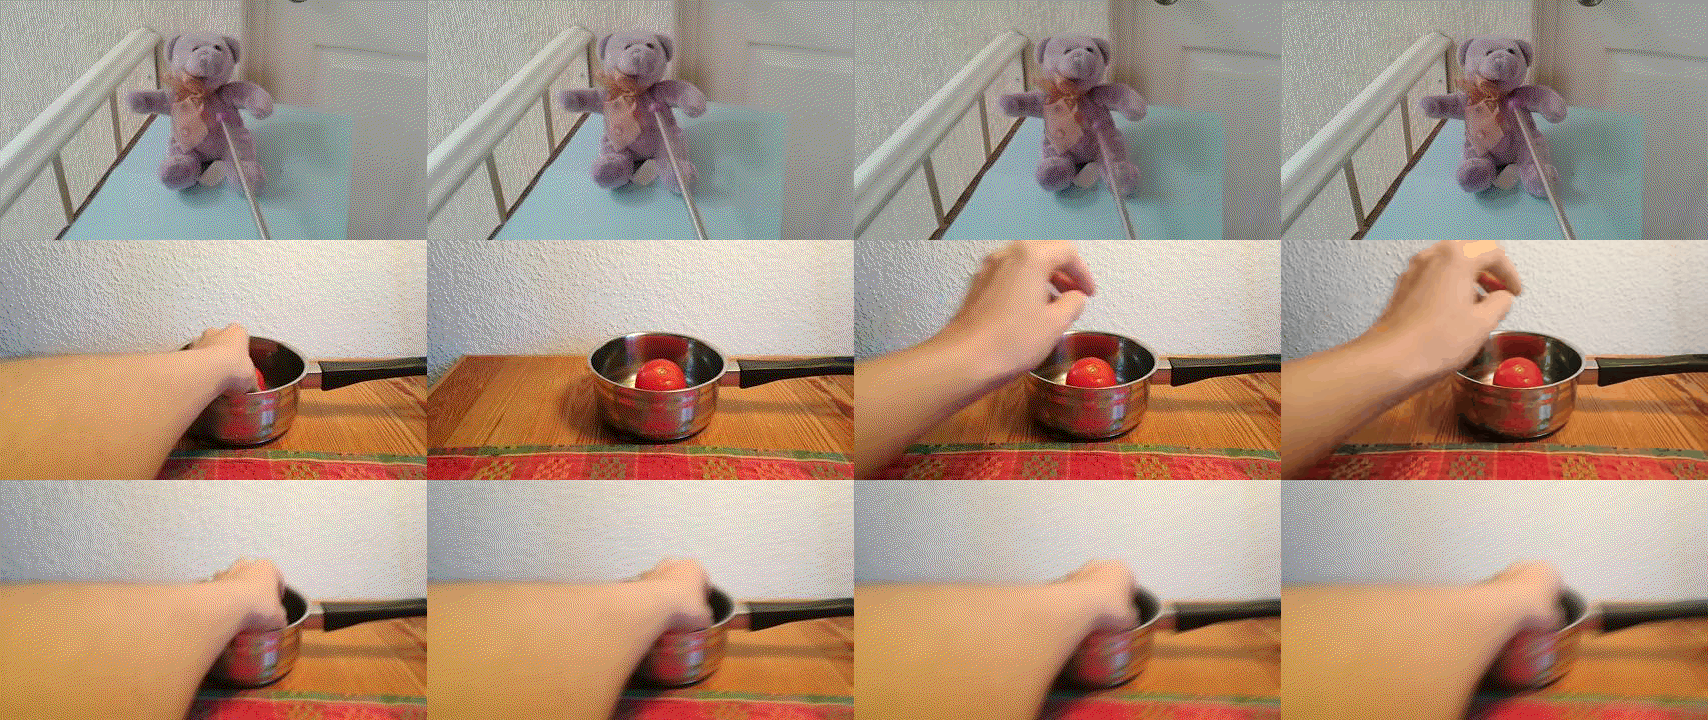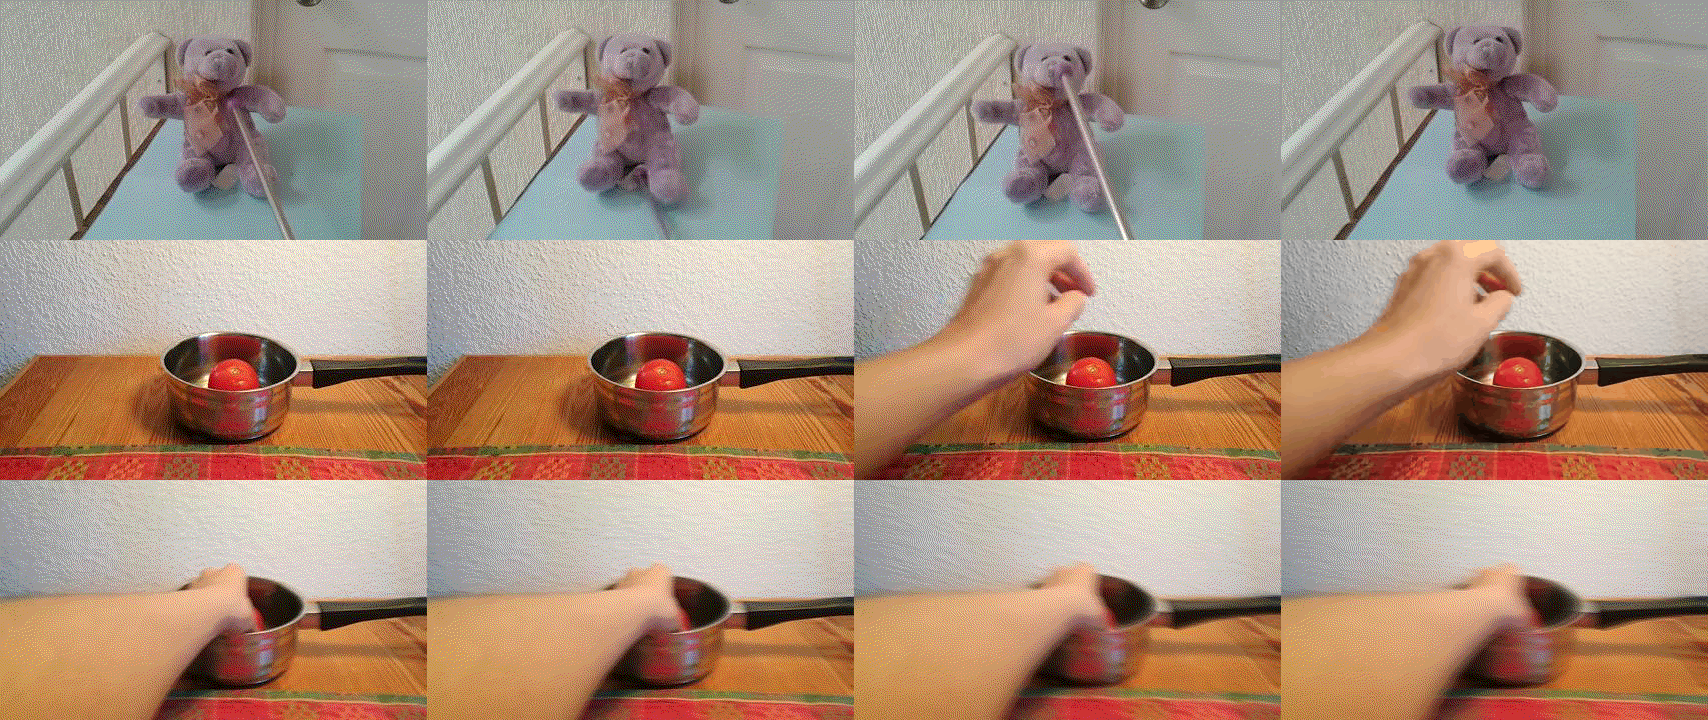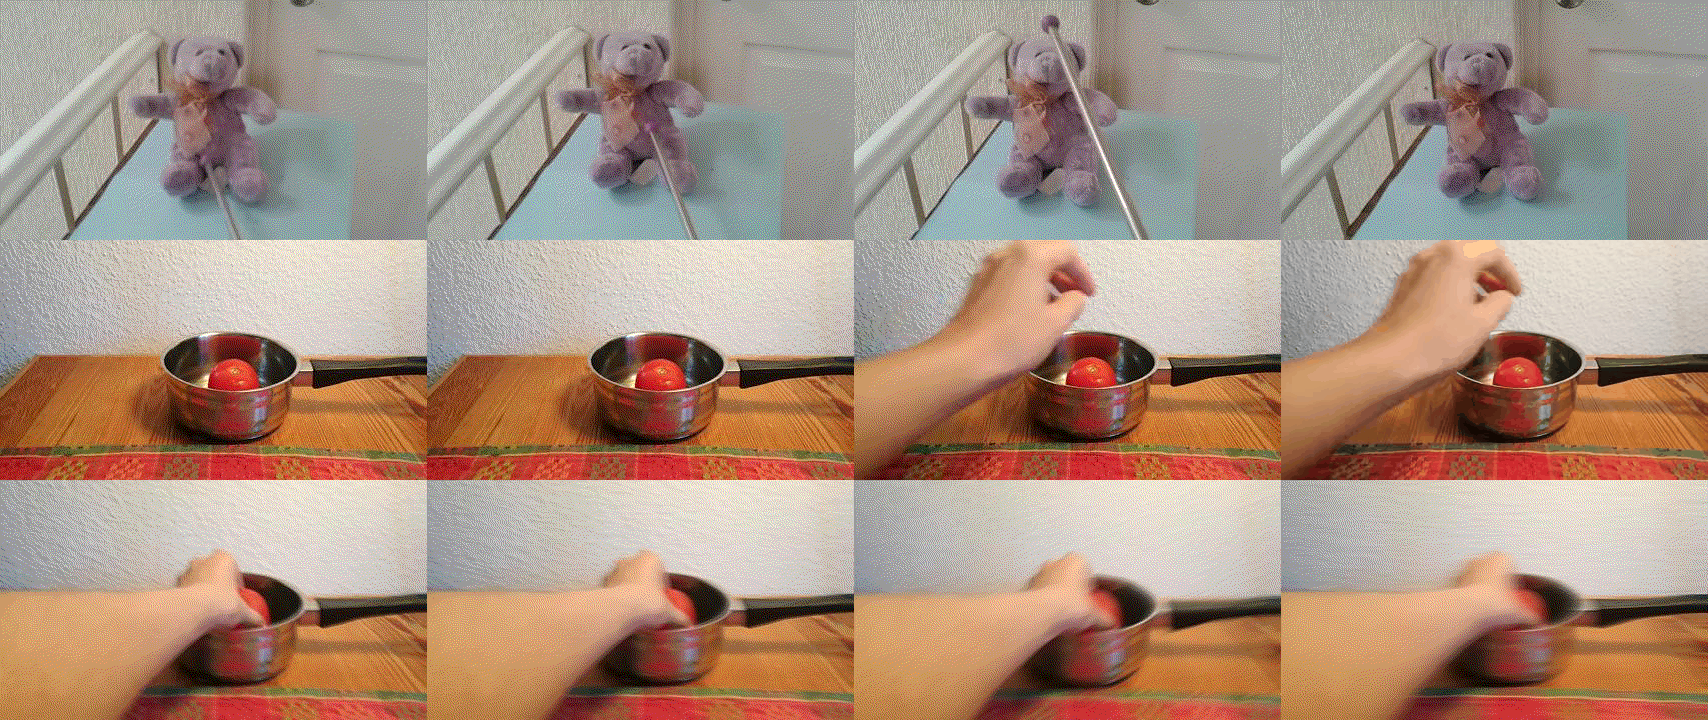
SSv2-P
| No. of classes | No. of Videos | Perturbations |
|---|---|---|
| 174 | 2,229,930 | 90 |
A Large-scale Robustness Analysis of Video Action Recognition Models
Madeline Chantry, Naman Biyani, Prudvi Kamtam, Shruti Vyas, Hamid Palangi, Vibhav Vineet, and Yogesh Singh Rawat
CVPR 2023
MSRVTT-P
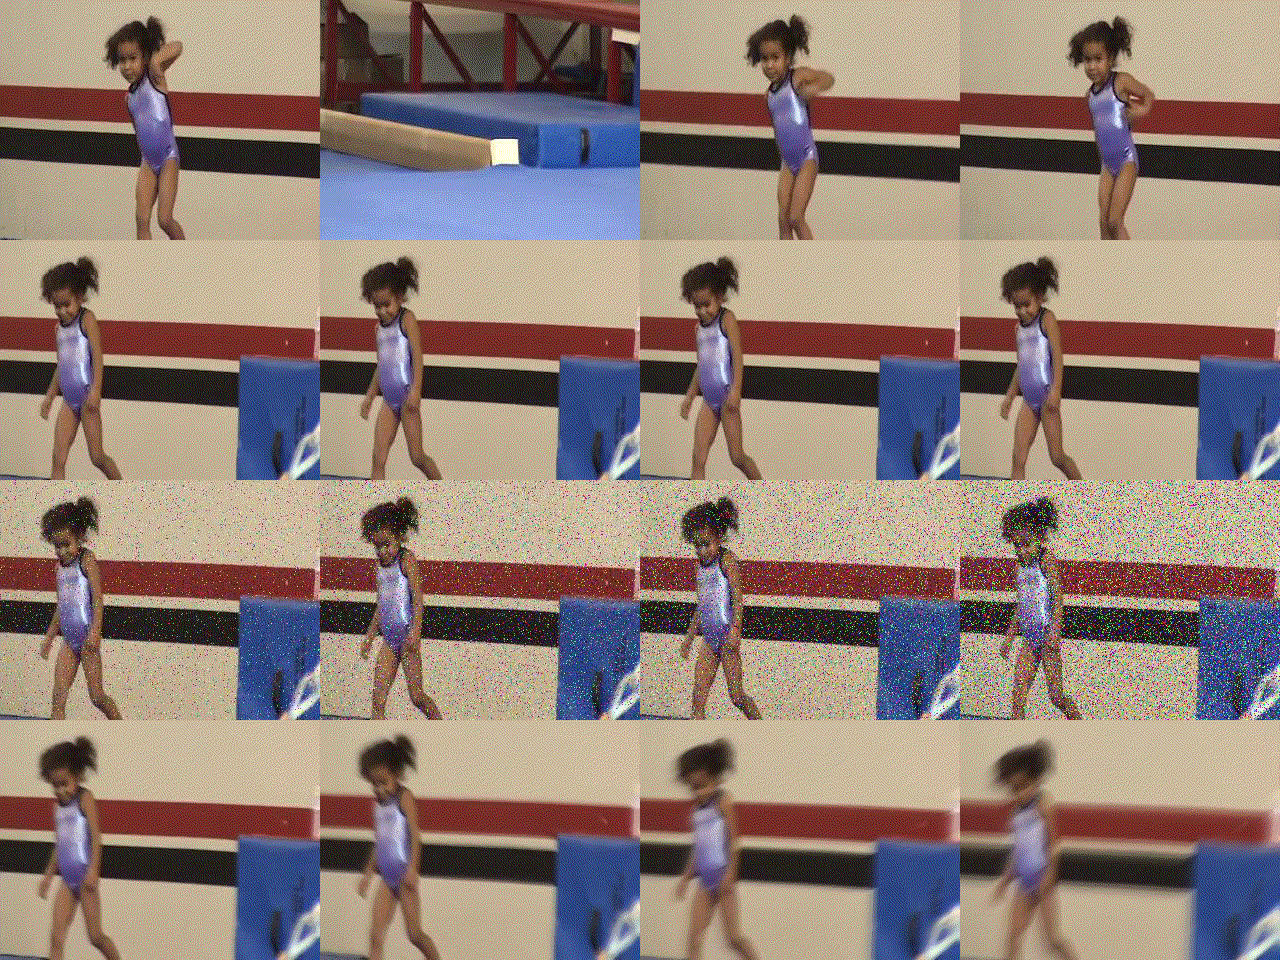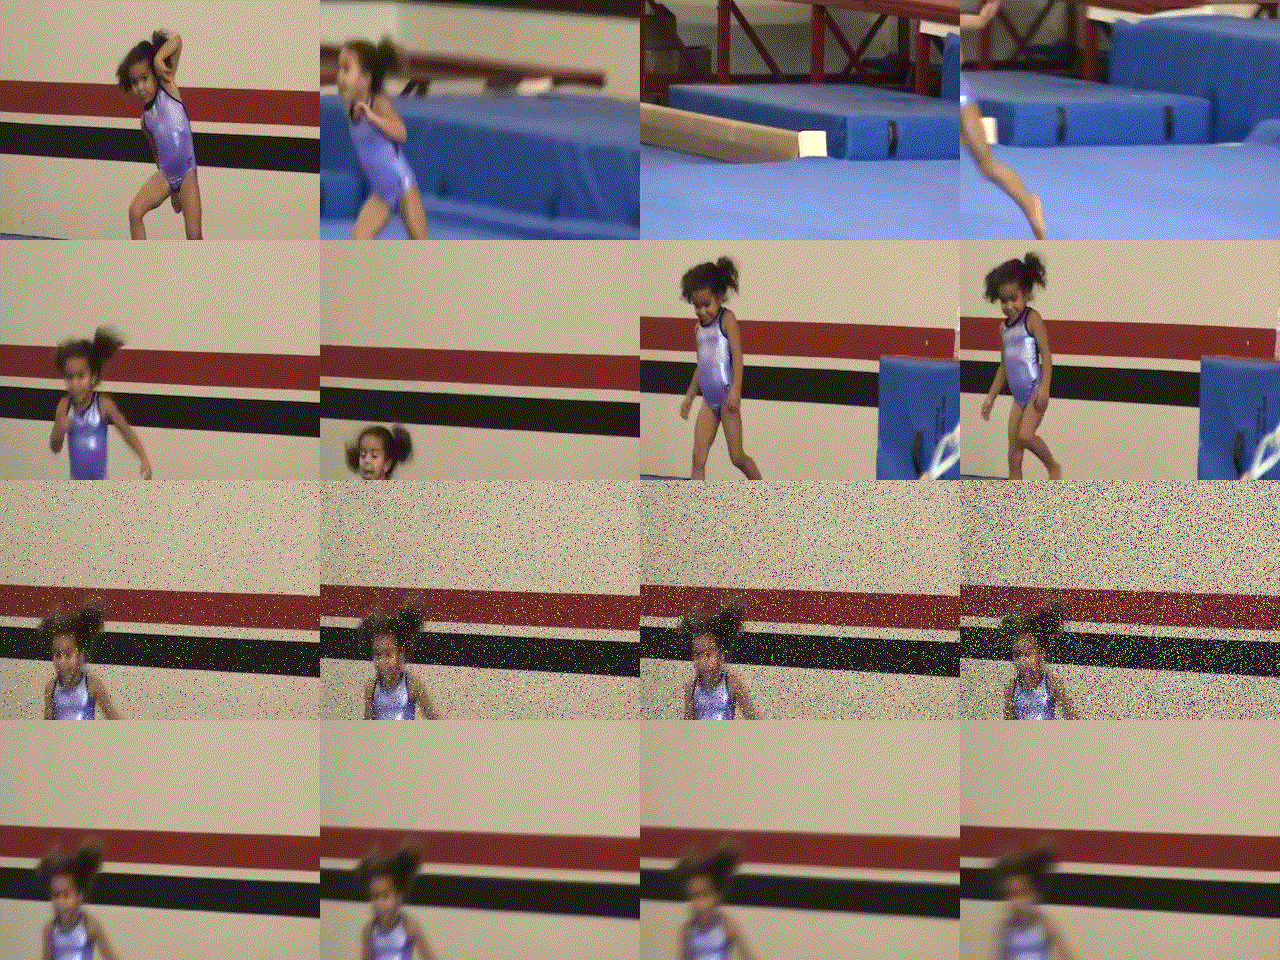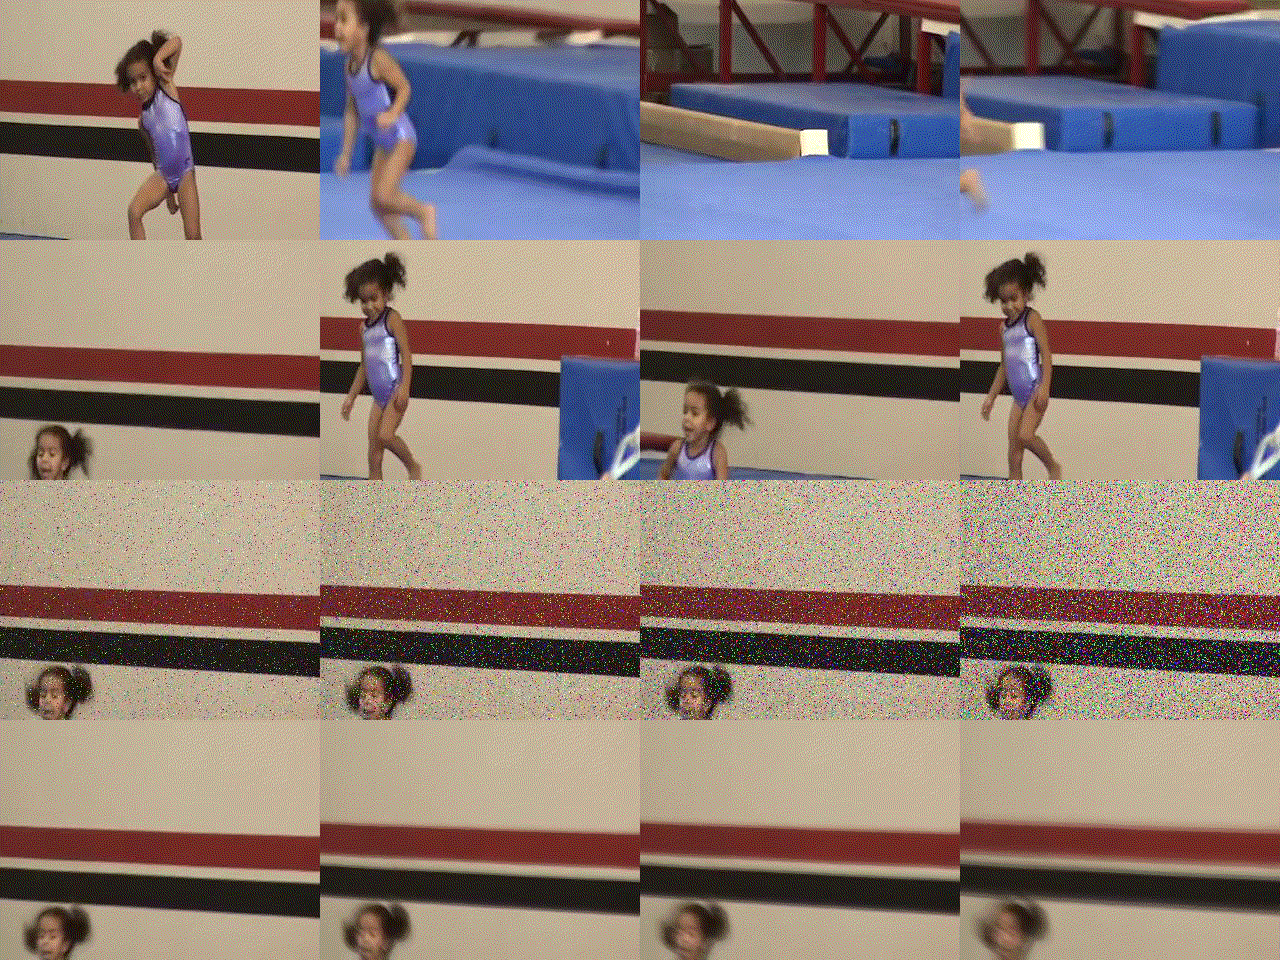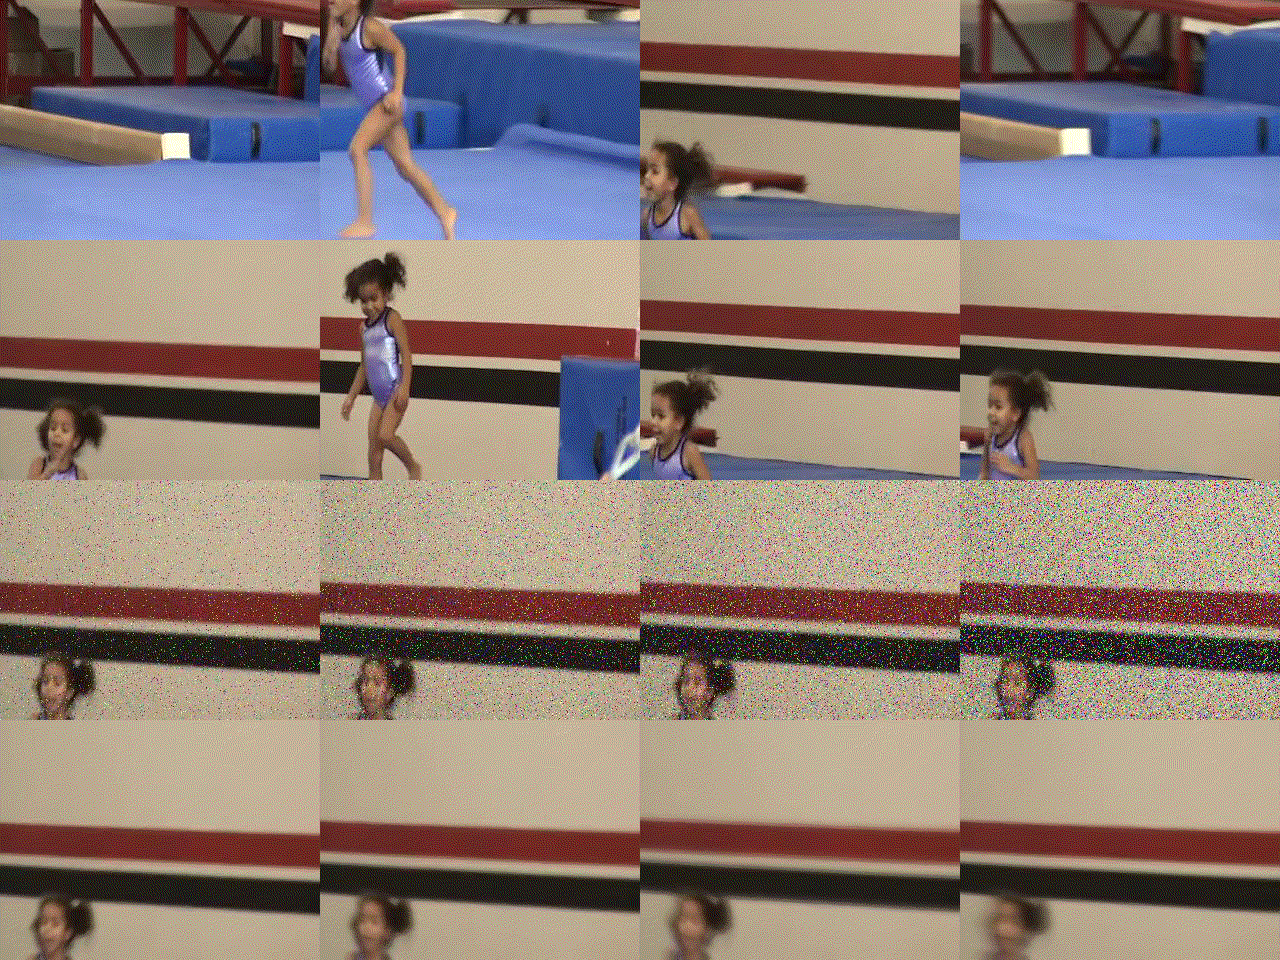
| Videos | Captions | Video-Text Pairs |
|---|---|---|
| 90K | 35K | 2,766K |
Robustness Analysis of Video-Language Models Against Visual and Language Perturbations
Madeline C. Schiappa, Shruti Vyas, Hamid Palangi, Yogesh S. Rawat, and Vibhav Vineet
NeurIPS 2022
You2Cook-P
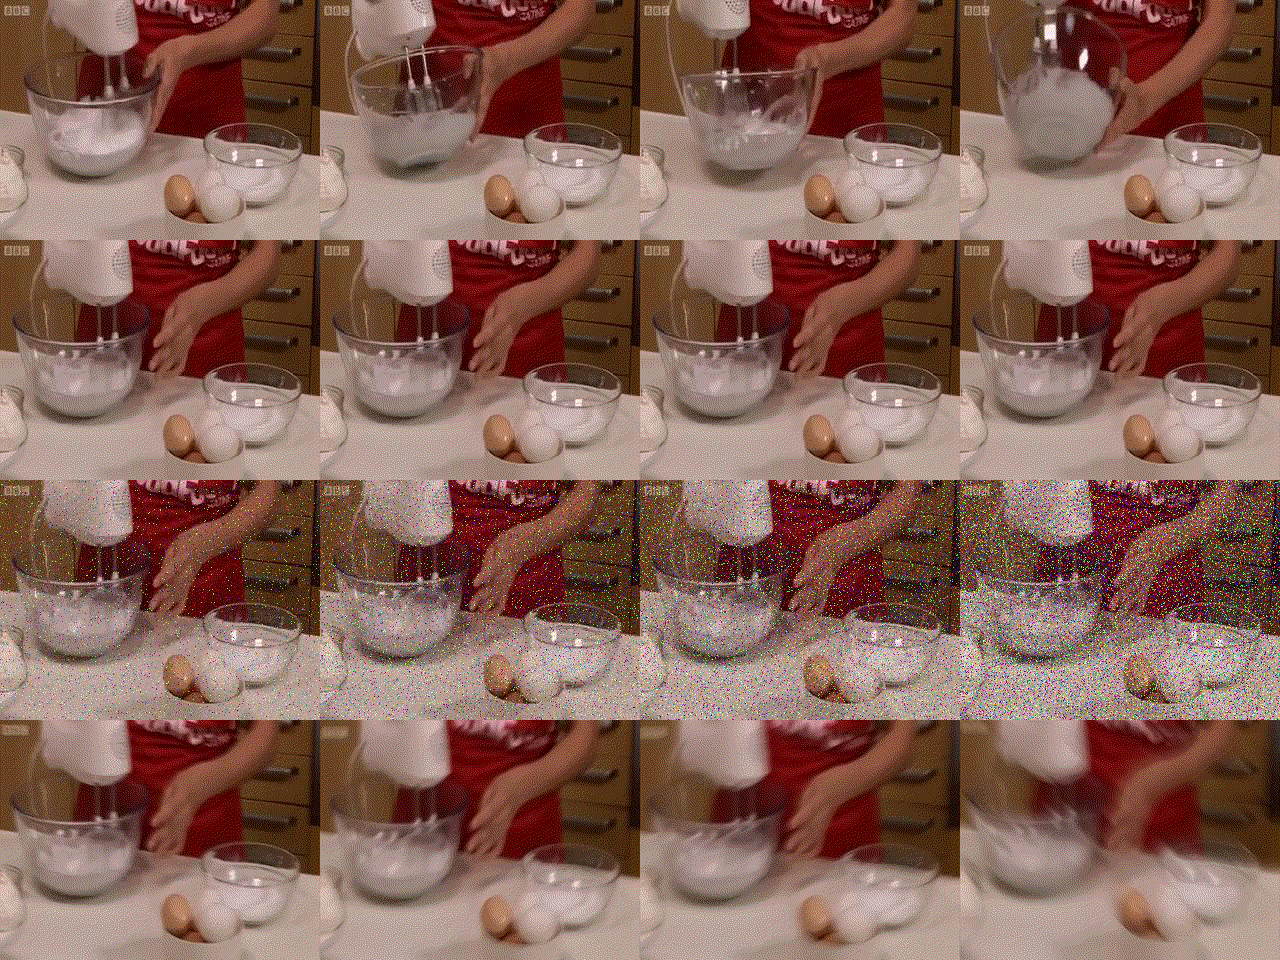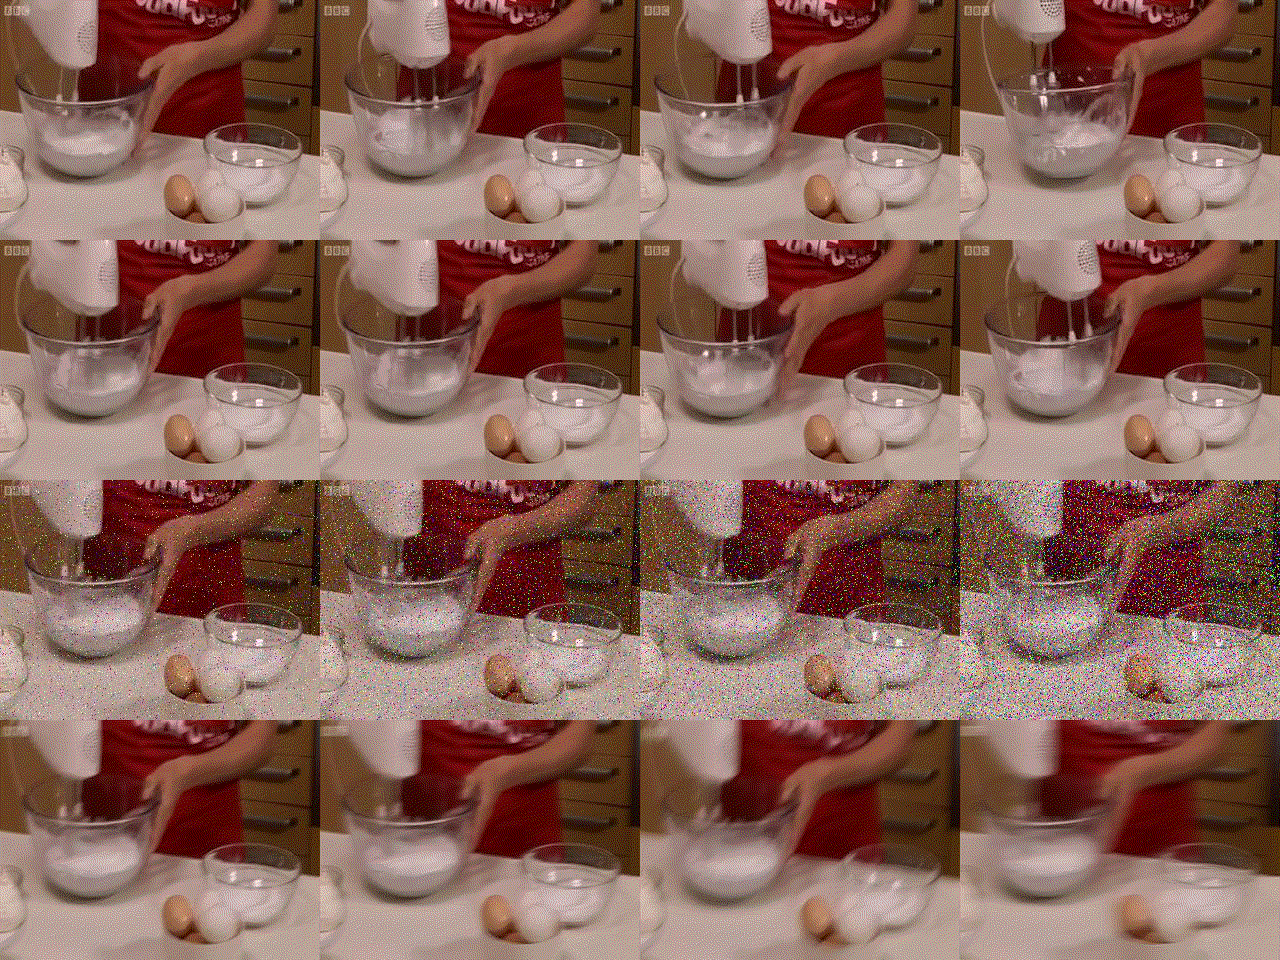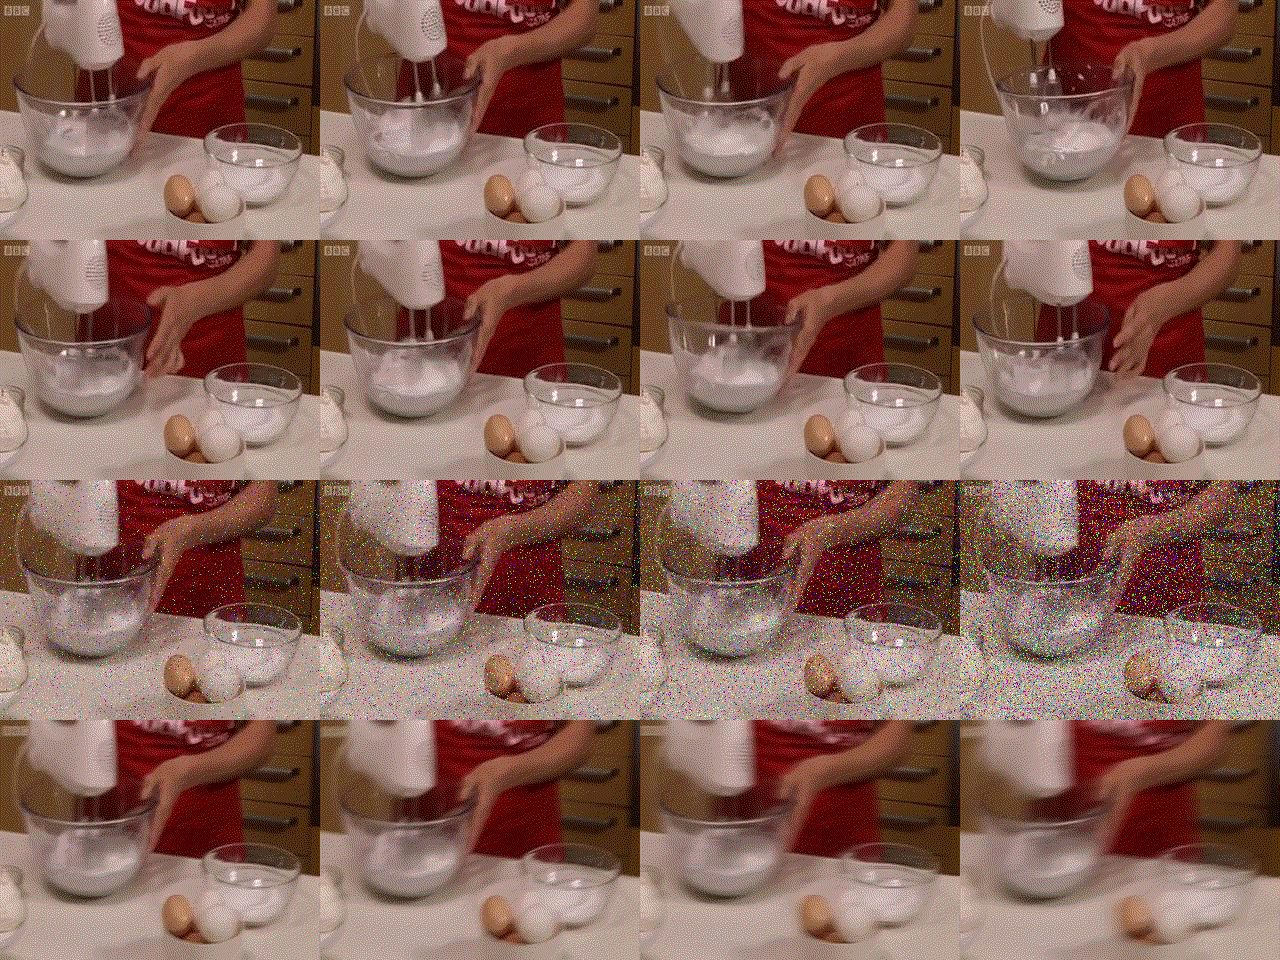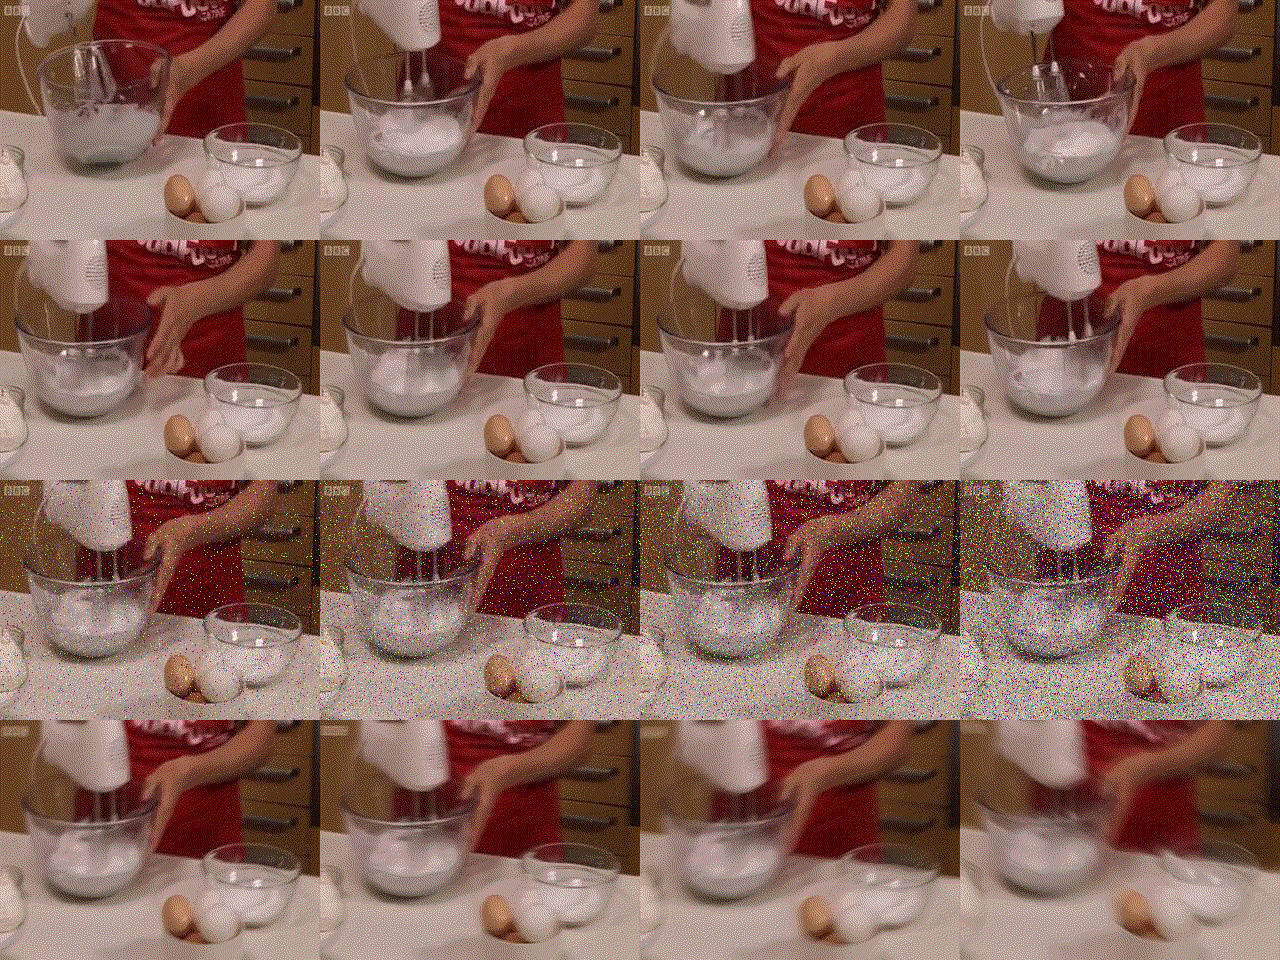
| Videos | Captions | Video-Text Pairs |
|---|---|---|
| 41K | 103K | 9,266K |
Robustness Analysis of Video-Language Models Against Visual and Language Perturbations
Madeline C. Schiappa, Shruti Vyas, Hamid Palangi, Yogesh S. Rawat, and Vibhav Vineet
NeurIPS 2022
Occlusion
O-UCF
| No. of Videos | No. of Classes | No. of Instances |
|---|---|---|
| 20306 | 24 | 2284 |
On Occlusions in Video Action Detection: Benchmark Datasets And Training Recipes
Rajat Modi, Vibhav Vineet, and Yogesh Singh Rawat
NeurIPS 2023
O-JHMDB
| No. of Videos | No. of Classes | No. of Instances |
|---|---|---|
| 20306 | 24 | 2284 |
On Occlusions in Video Action Detection: Benchmark Datasets And Training Recipes
Rajat Modi, Vibhav Vineet, and Yogesh Singh Rawat
NeurIPS 2023
OVIS-UCF
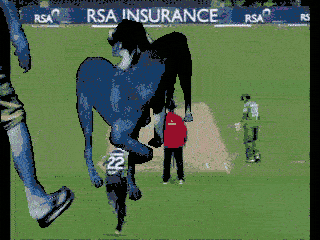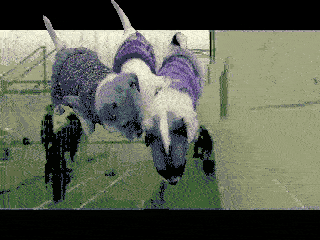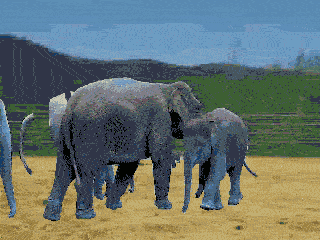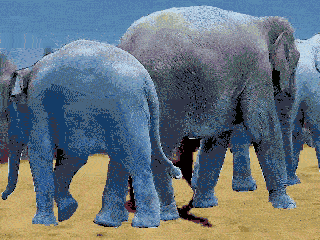
| No. of Videos | No. of Classes | No. of Instances |
|---|---|---|
| 5896 | 21 | 928 |
On Occlusions in Video Action Detection: Benchmark Datasets And Training Recipes
Rajat Modi, Vibhav Vineet, and Yogesh Singh Rawat
NeurIPS 2023
OVIS-JHMDB
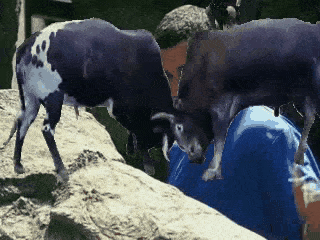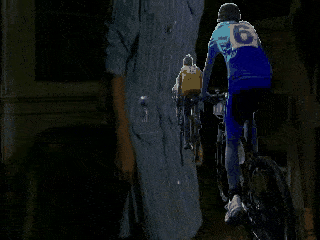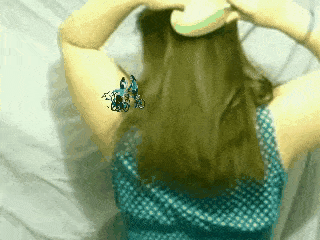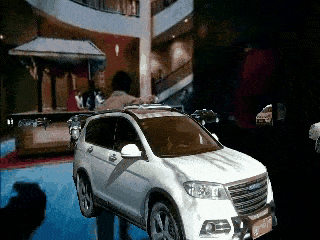
| No. of Videos | No. of Classes | No. of Instances |
|---|---|---|
| 5896 | 21 | 928 |
On Occlusions in Video Action Detection: Benchmark Datasets And Training Recipes
Rajat Modi, Vibhav Vineet, and Yogesh Singh Rawat
NeurIPS 2023
Real-OUCF
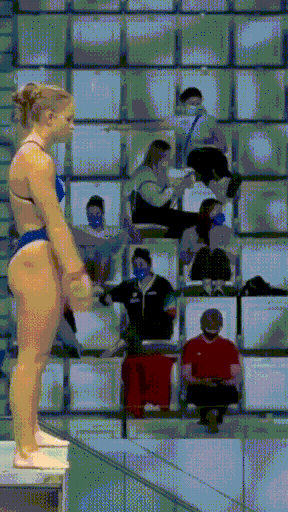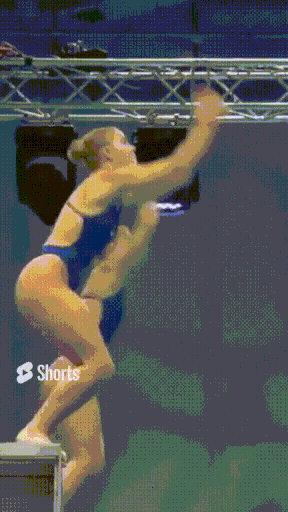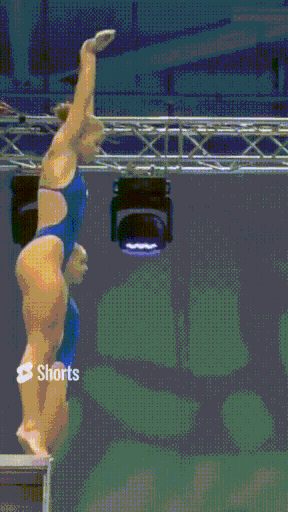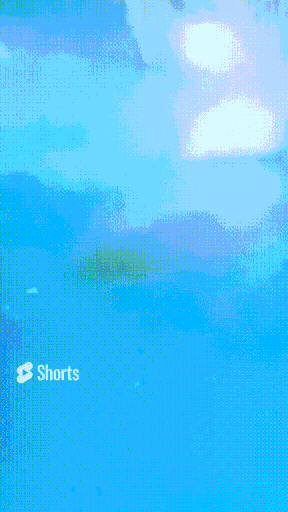
| No. of Videos | No. of Classes | No. of Instances |
|---|---|---|
| 1743 | 24 | 6920 |
On Occlusions in Video Action Detection: Benchmark Datasets And Training Recipes
Rajat Modi, Vibhav Vineet, and Yogesh Singh Rawat
NeurIPS 2023
UCF-101-O
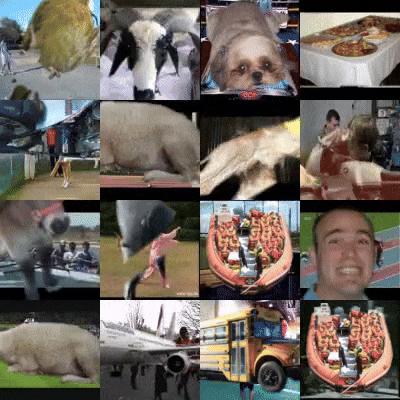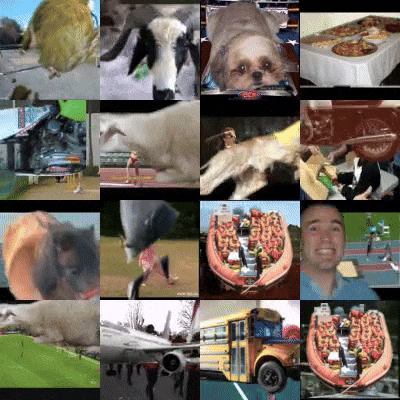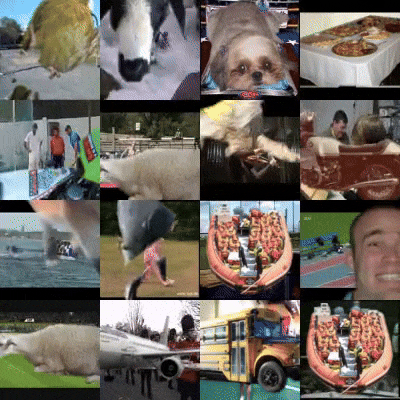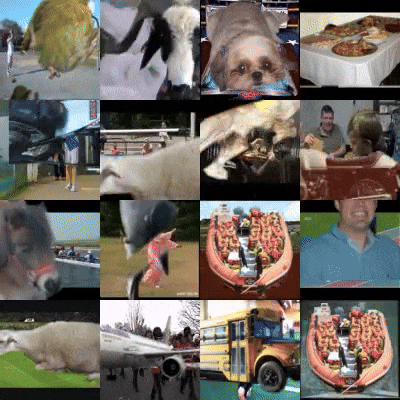
| No. of Videos | No. of Classes | Occlusion Size |
|---|---|---|
| 3783 | 101 | 40-60% |
Revealing the unseen: Benchmarking video action recognition under occlusion
Shresth Grover, Vibhav Vineet, and Yogesh S Rawat
NeurIPS 2023
K400-O
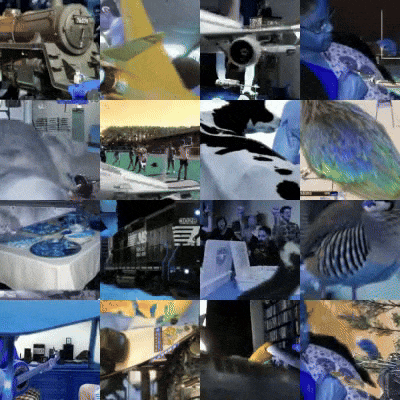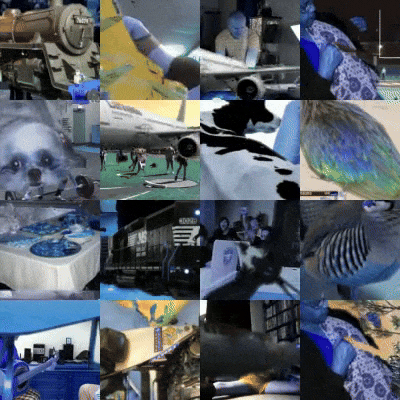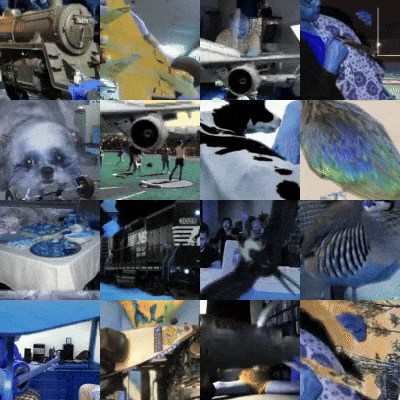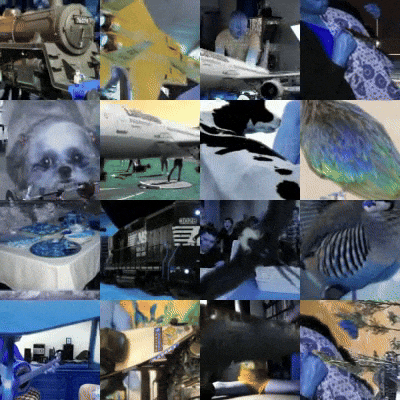
| No. of Videos | No. of Classes | Occlusion Size |
|---|---|---|
| 40,000 | 400 | 40-60% |
Revealing the unseen: Benchmarking video action recognition under occlusion
Shresth Grover, Vibhav Vineet, and Yogesh S Rawat
NeurIPS 2023
UCF-19-Y-OCC

| No. of Videos | No. of Classes | Duration |
|---|---|---|
| 570 | 19 | 5s |
Revealing the unseen: Benchmarking video action recognition under occlusion
Shresth Grover, Vibhav Vineet, and Yogesh S Rawat
NeurIPS 2023
Low Resolution
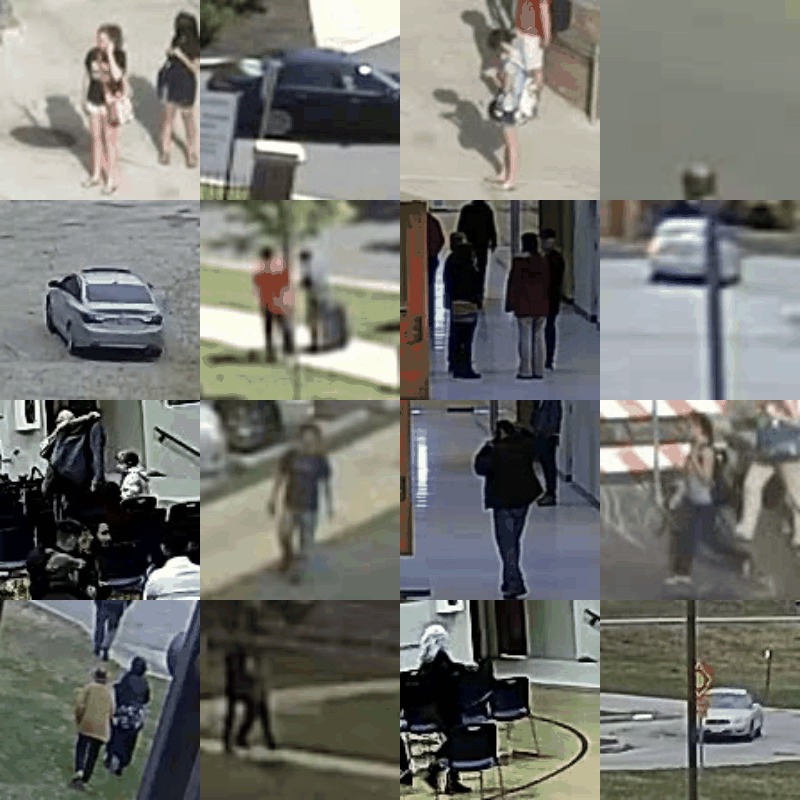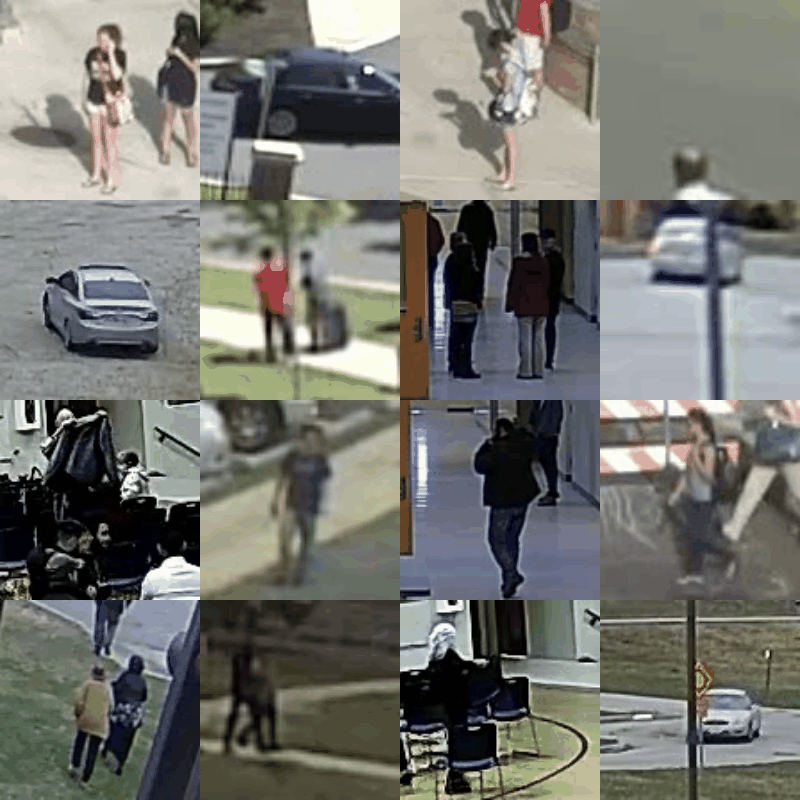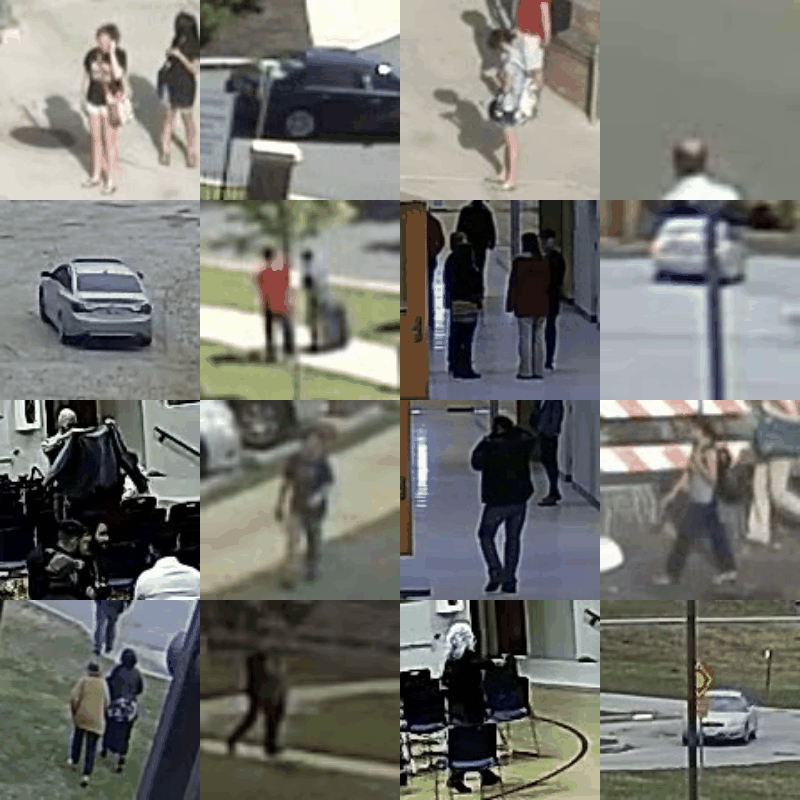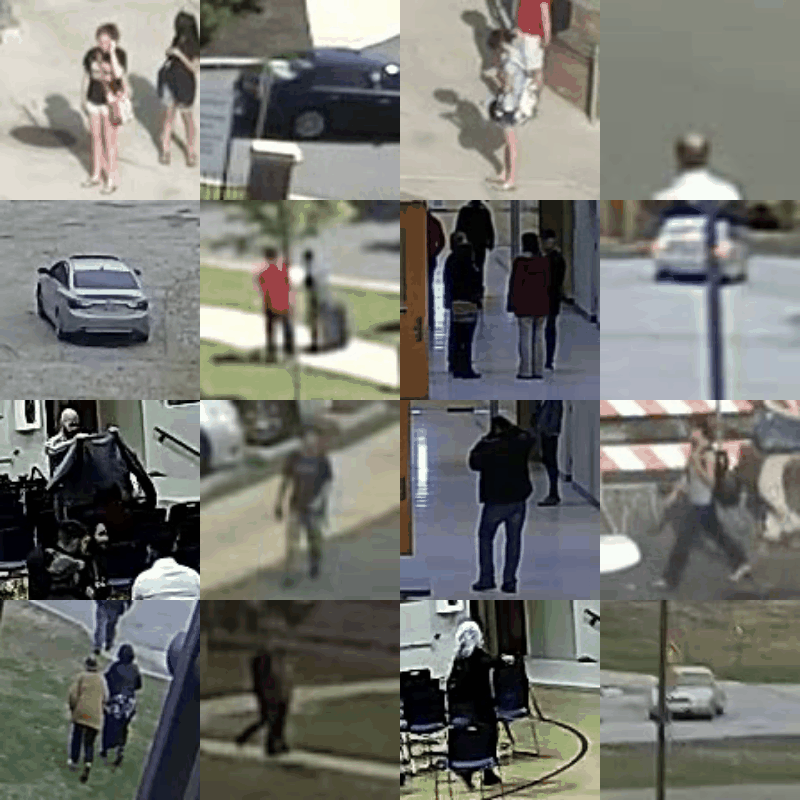
TinyVIRAT: Low-resolution Video Action Recognition
| Resolution | No. of Videos | No. of Classes | Label Type |
|---|---|---|---|
| 10×10 – 128×128 | 12,829 | 26 | Multi-Label |
TinyVIRAT: Low-resolution Video Action Recognition
Ugur Demir, Yogesh S Rawat, and Mubarak Shah
CVPR 2021 Workshop
Action Detection
UCF-MAMA [Multi Actor Multi Action]
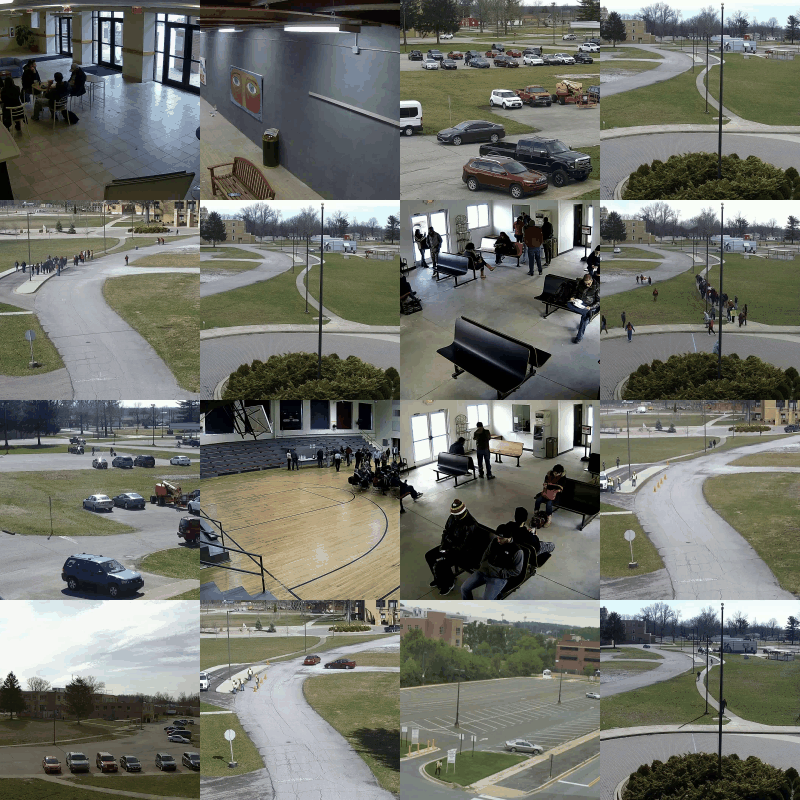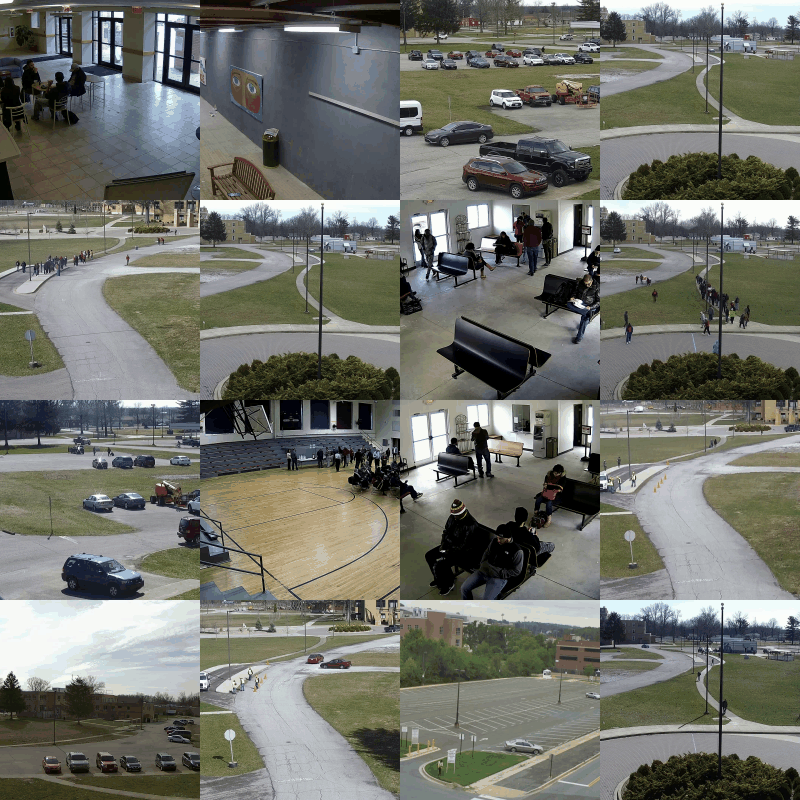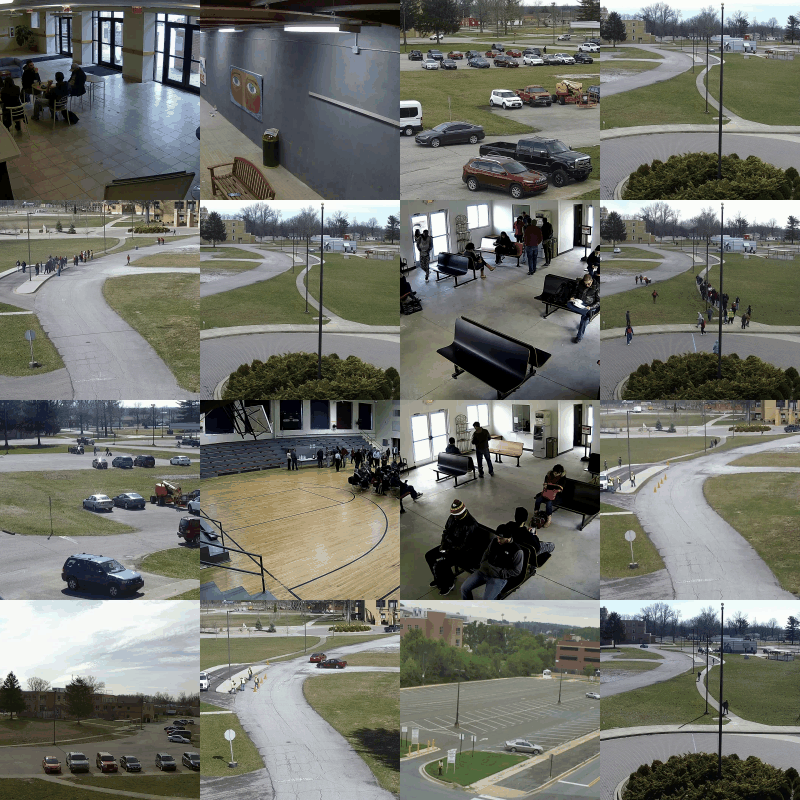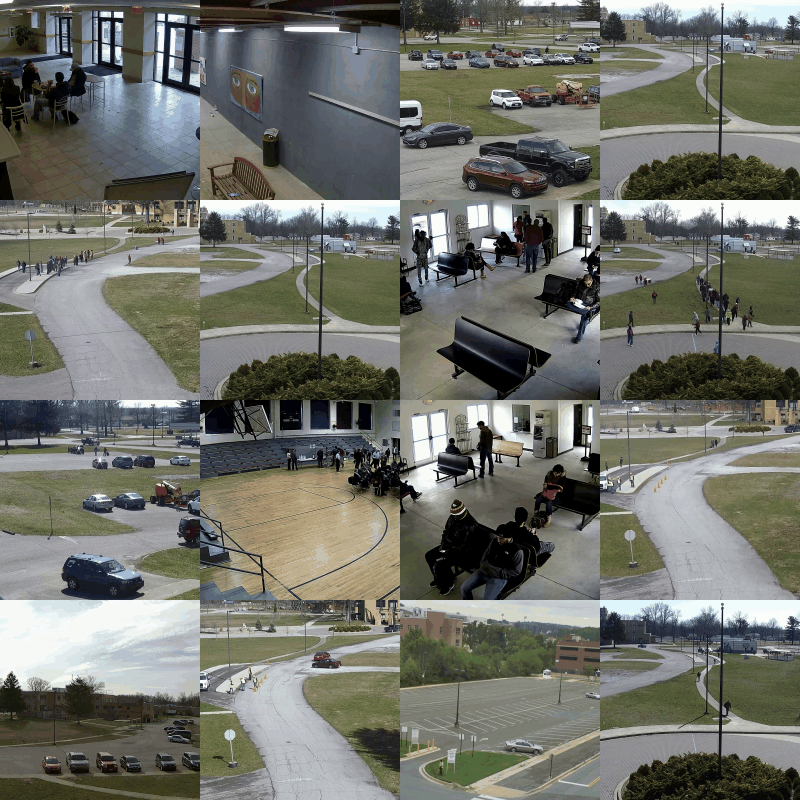
| Resolution | No. of Videos | No. of Classes | Label Type |
|---|---|---|---|
| 1920×1080 | 32,726 | 35 | Multi-Label |
Video Action Detection: Analysing Limitations and Challenges
Rajat Modi, Aayush Jung Rana, Akash Kumar, Praveen Tirupattur, Shruti Vyas, Yogesh Singh Rawat, Mubarak Shah
CVPR Workshop 2022
Perception
Probe-RCB: Relational, Compositional and Contextual Understanding
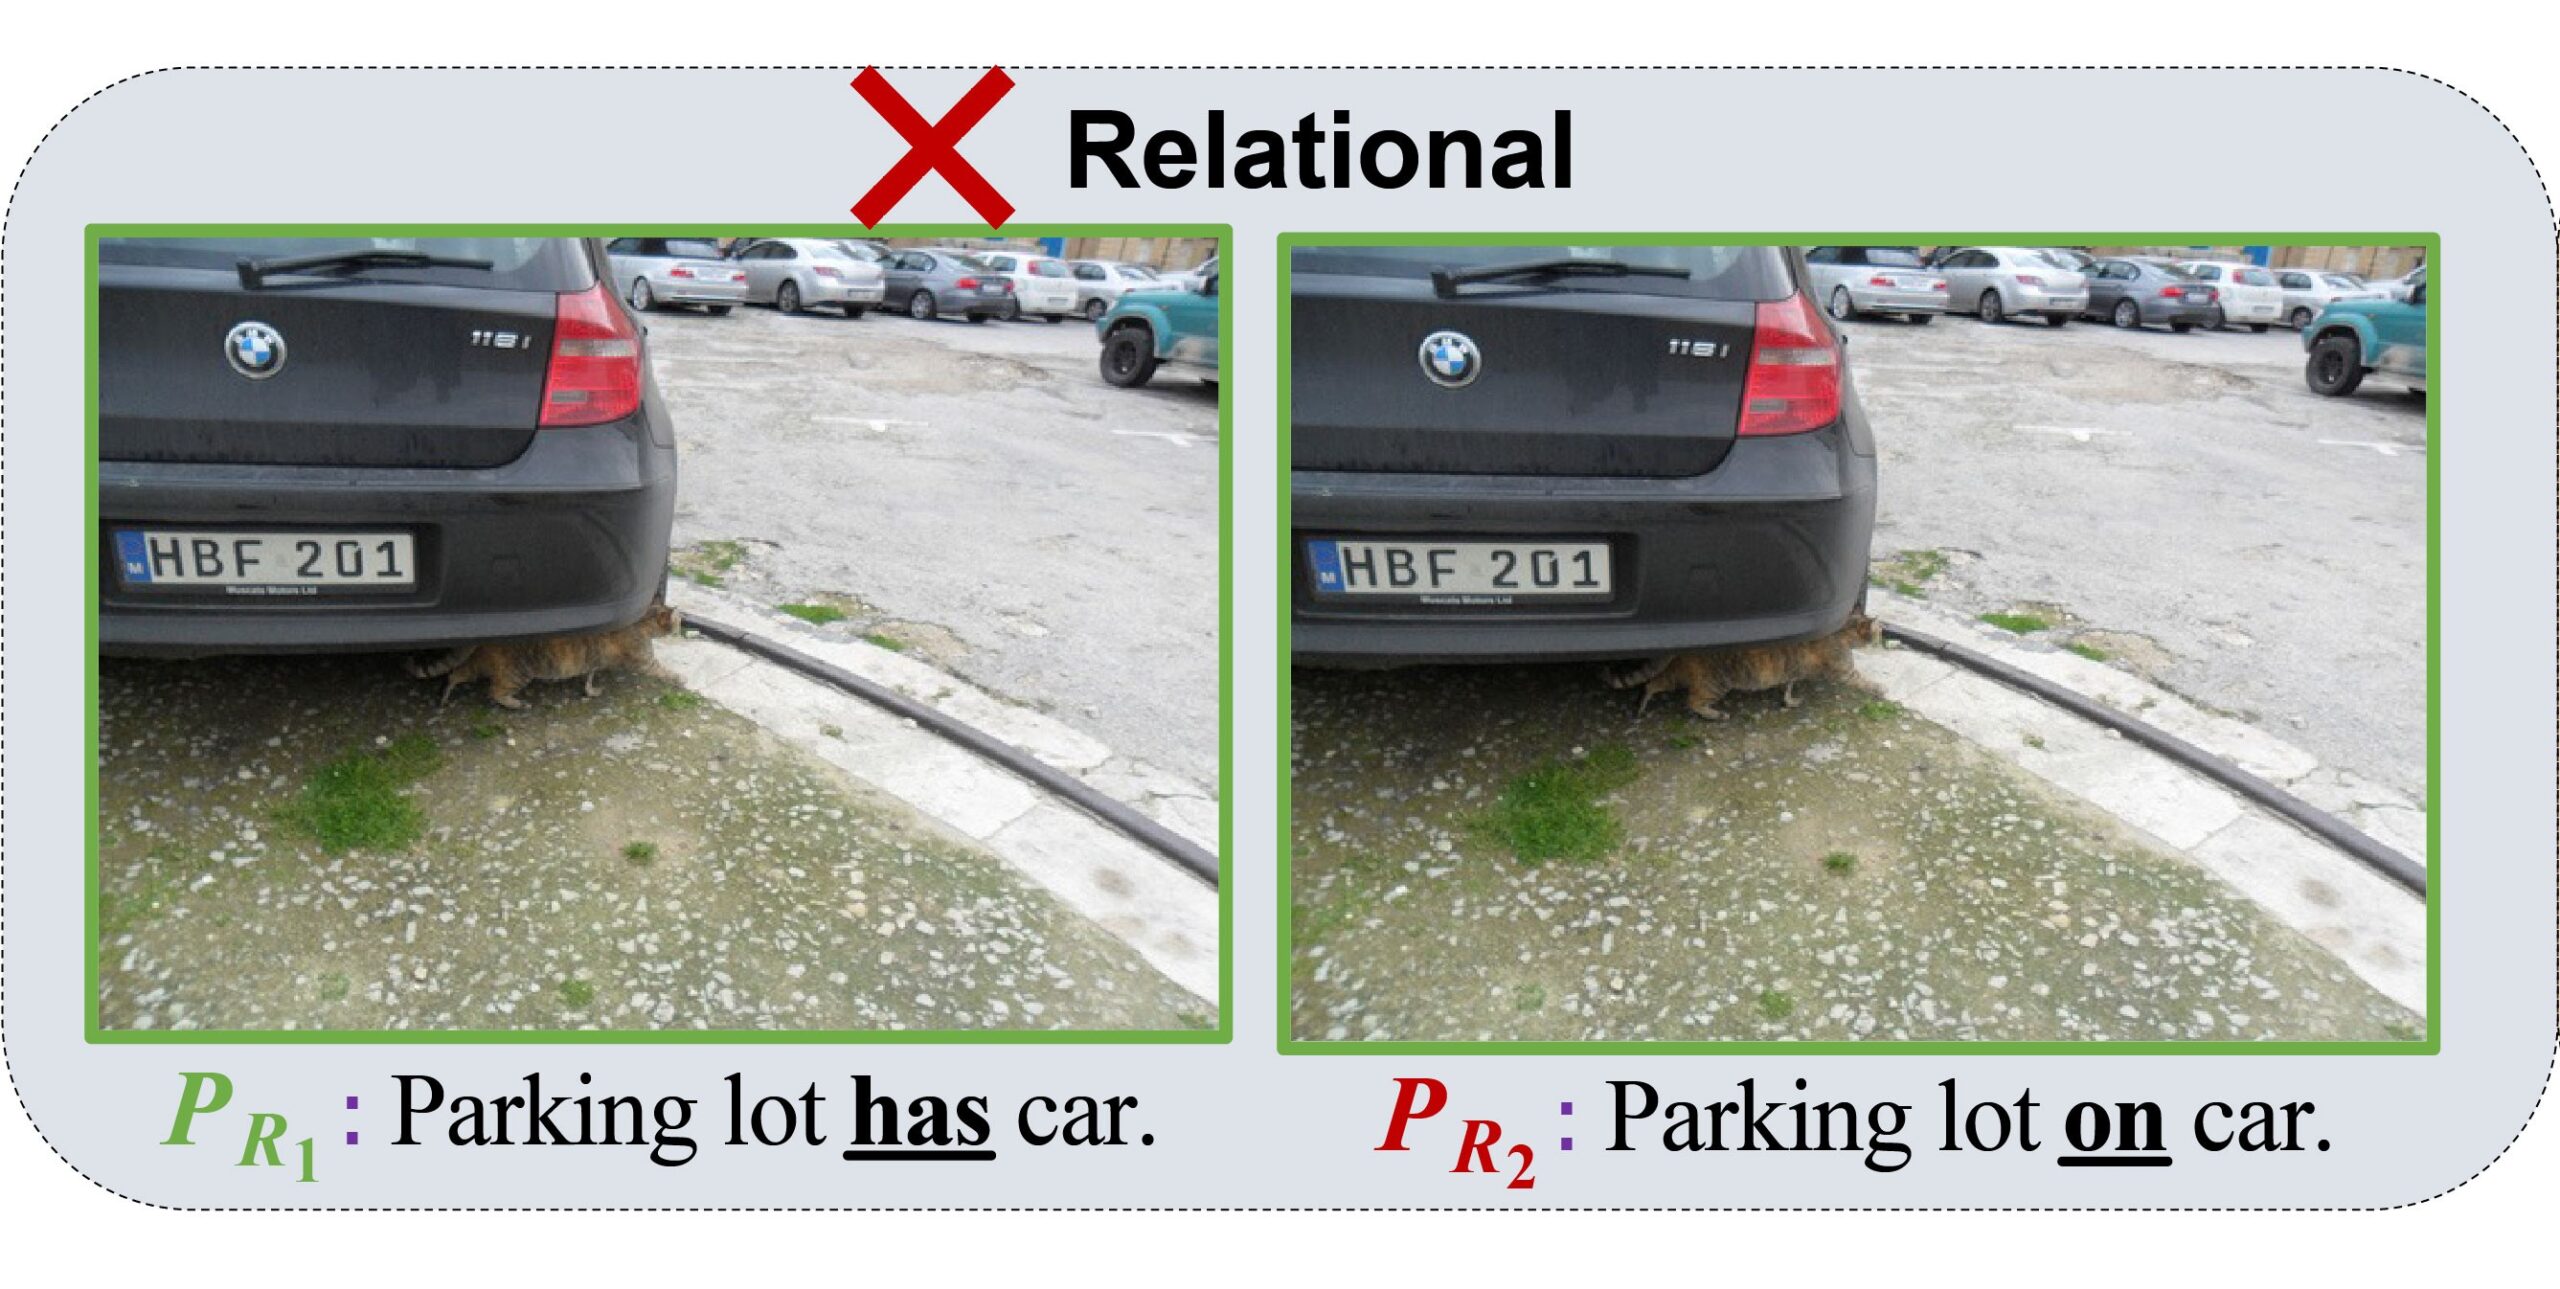
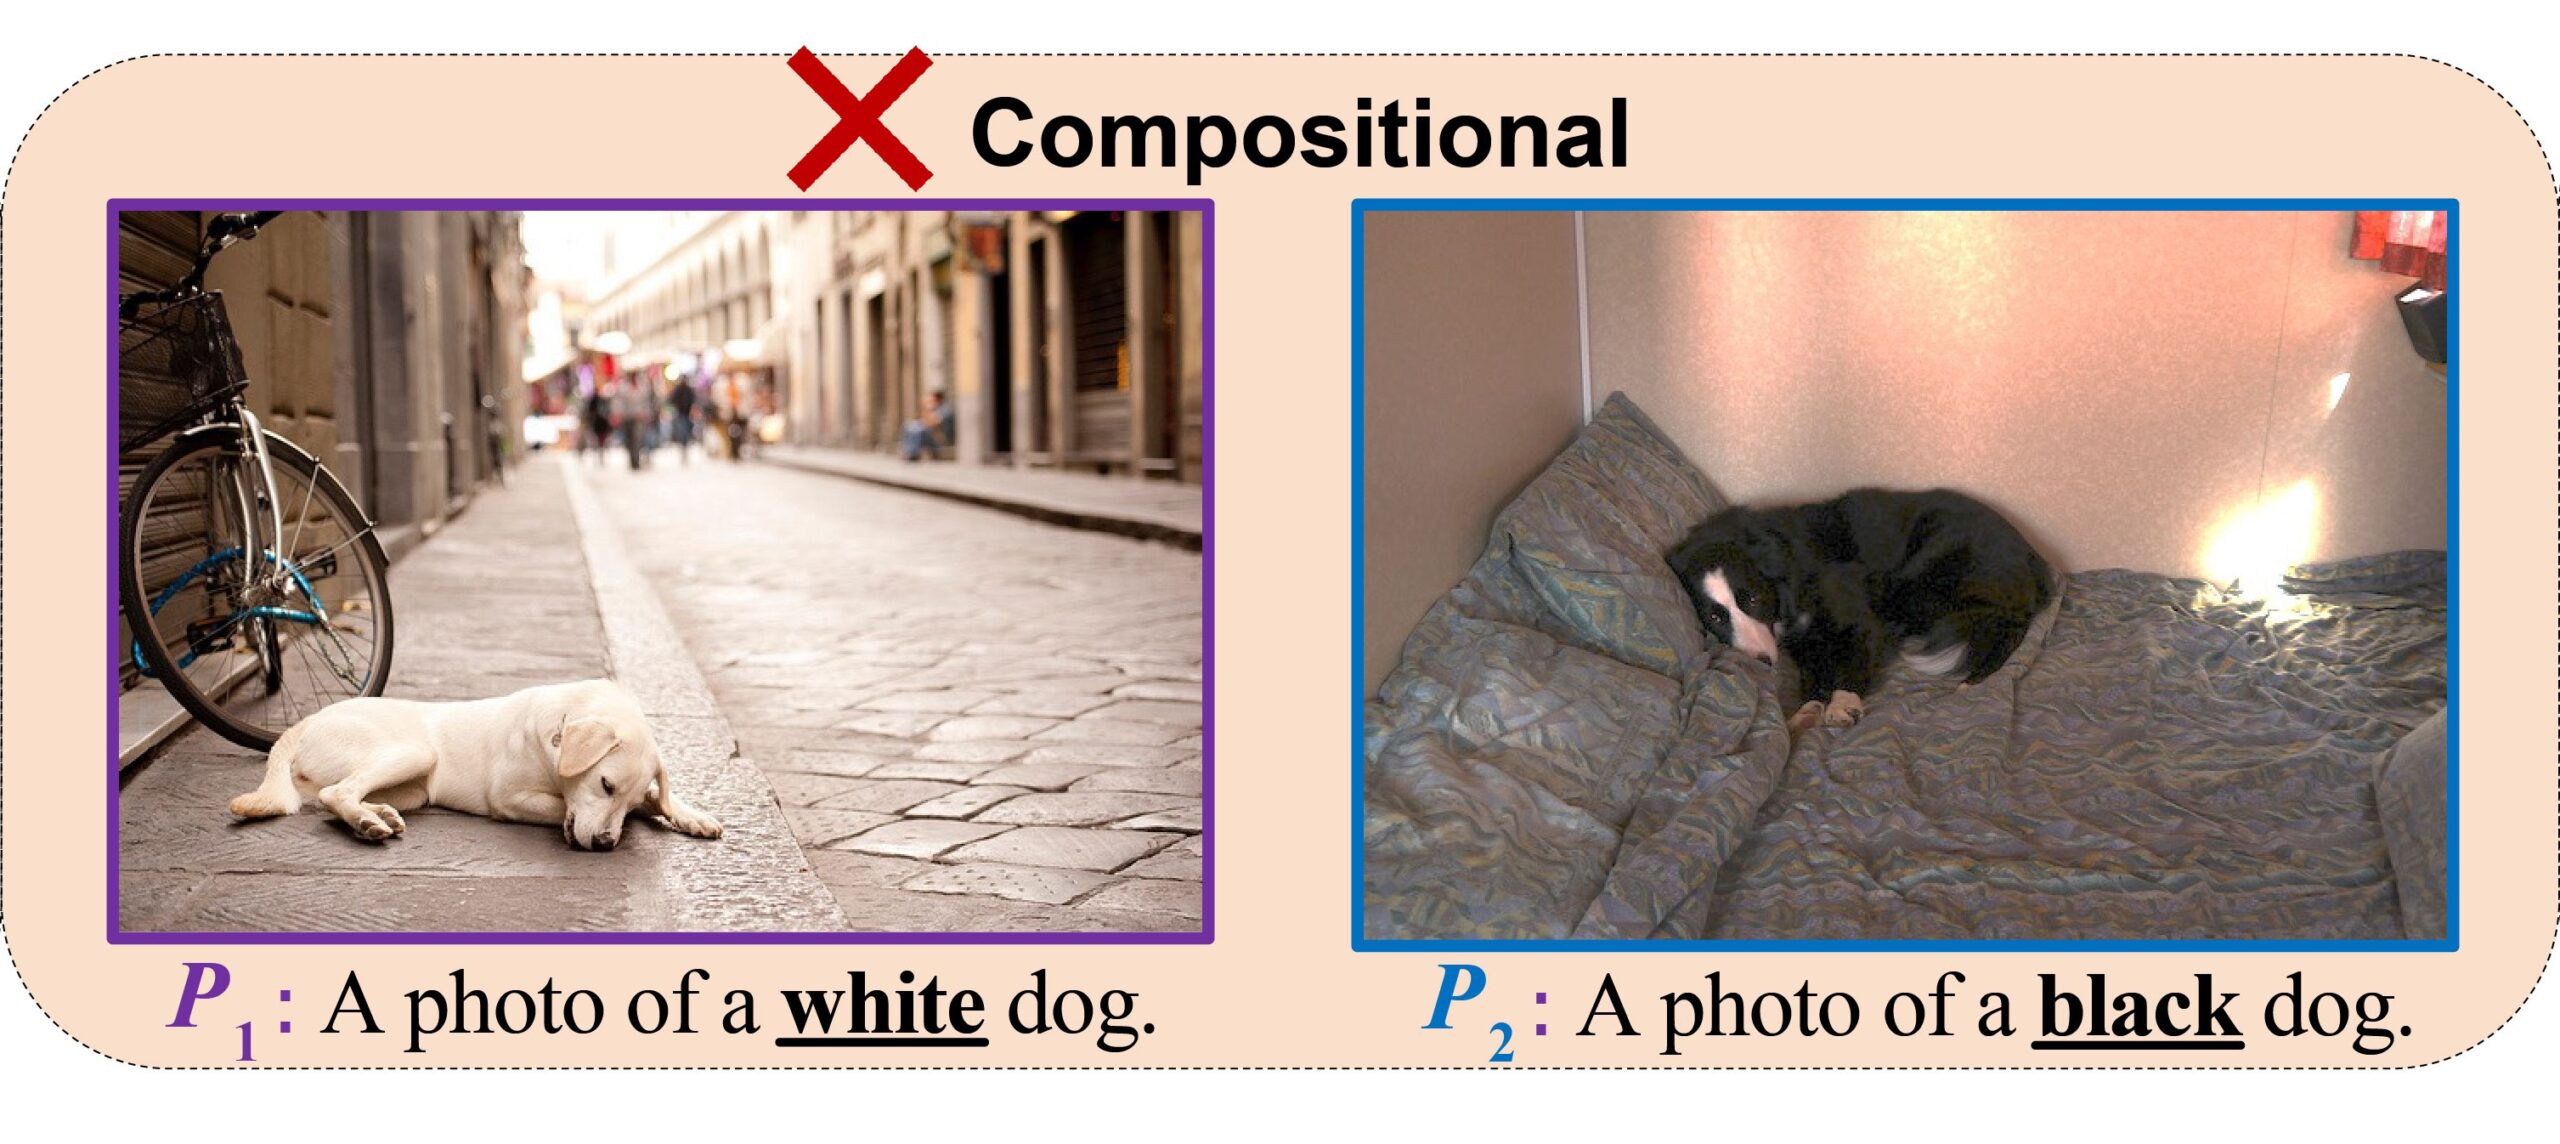
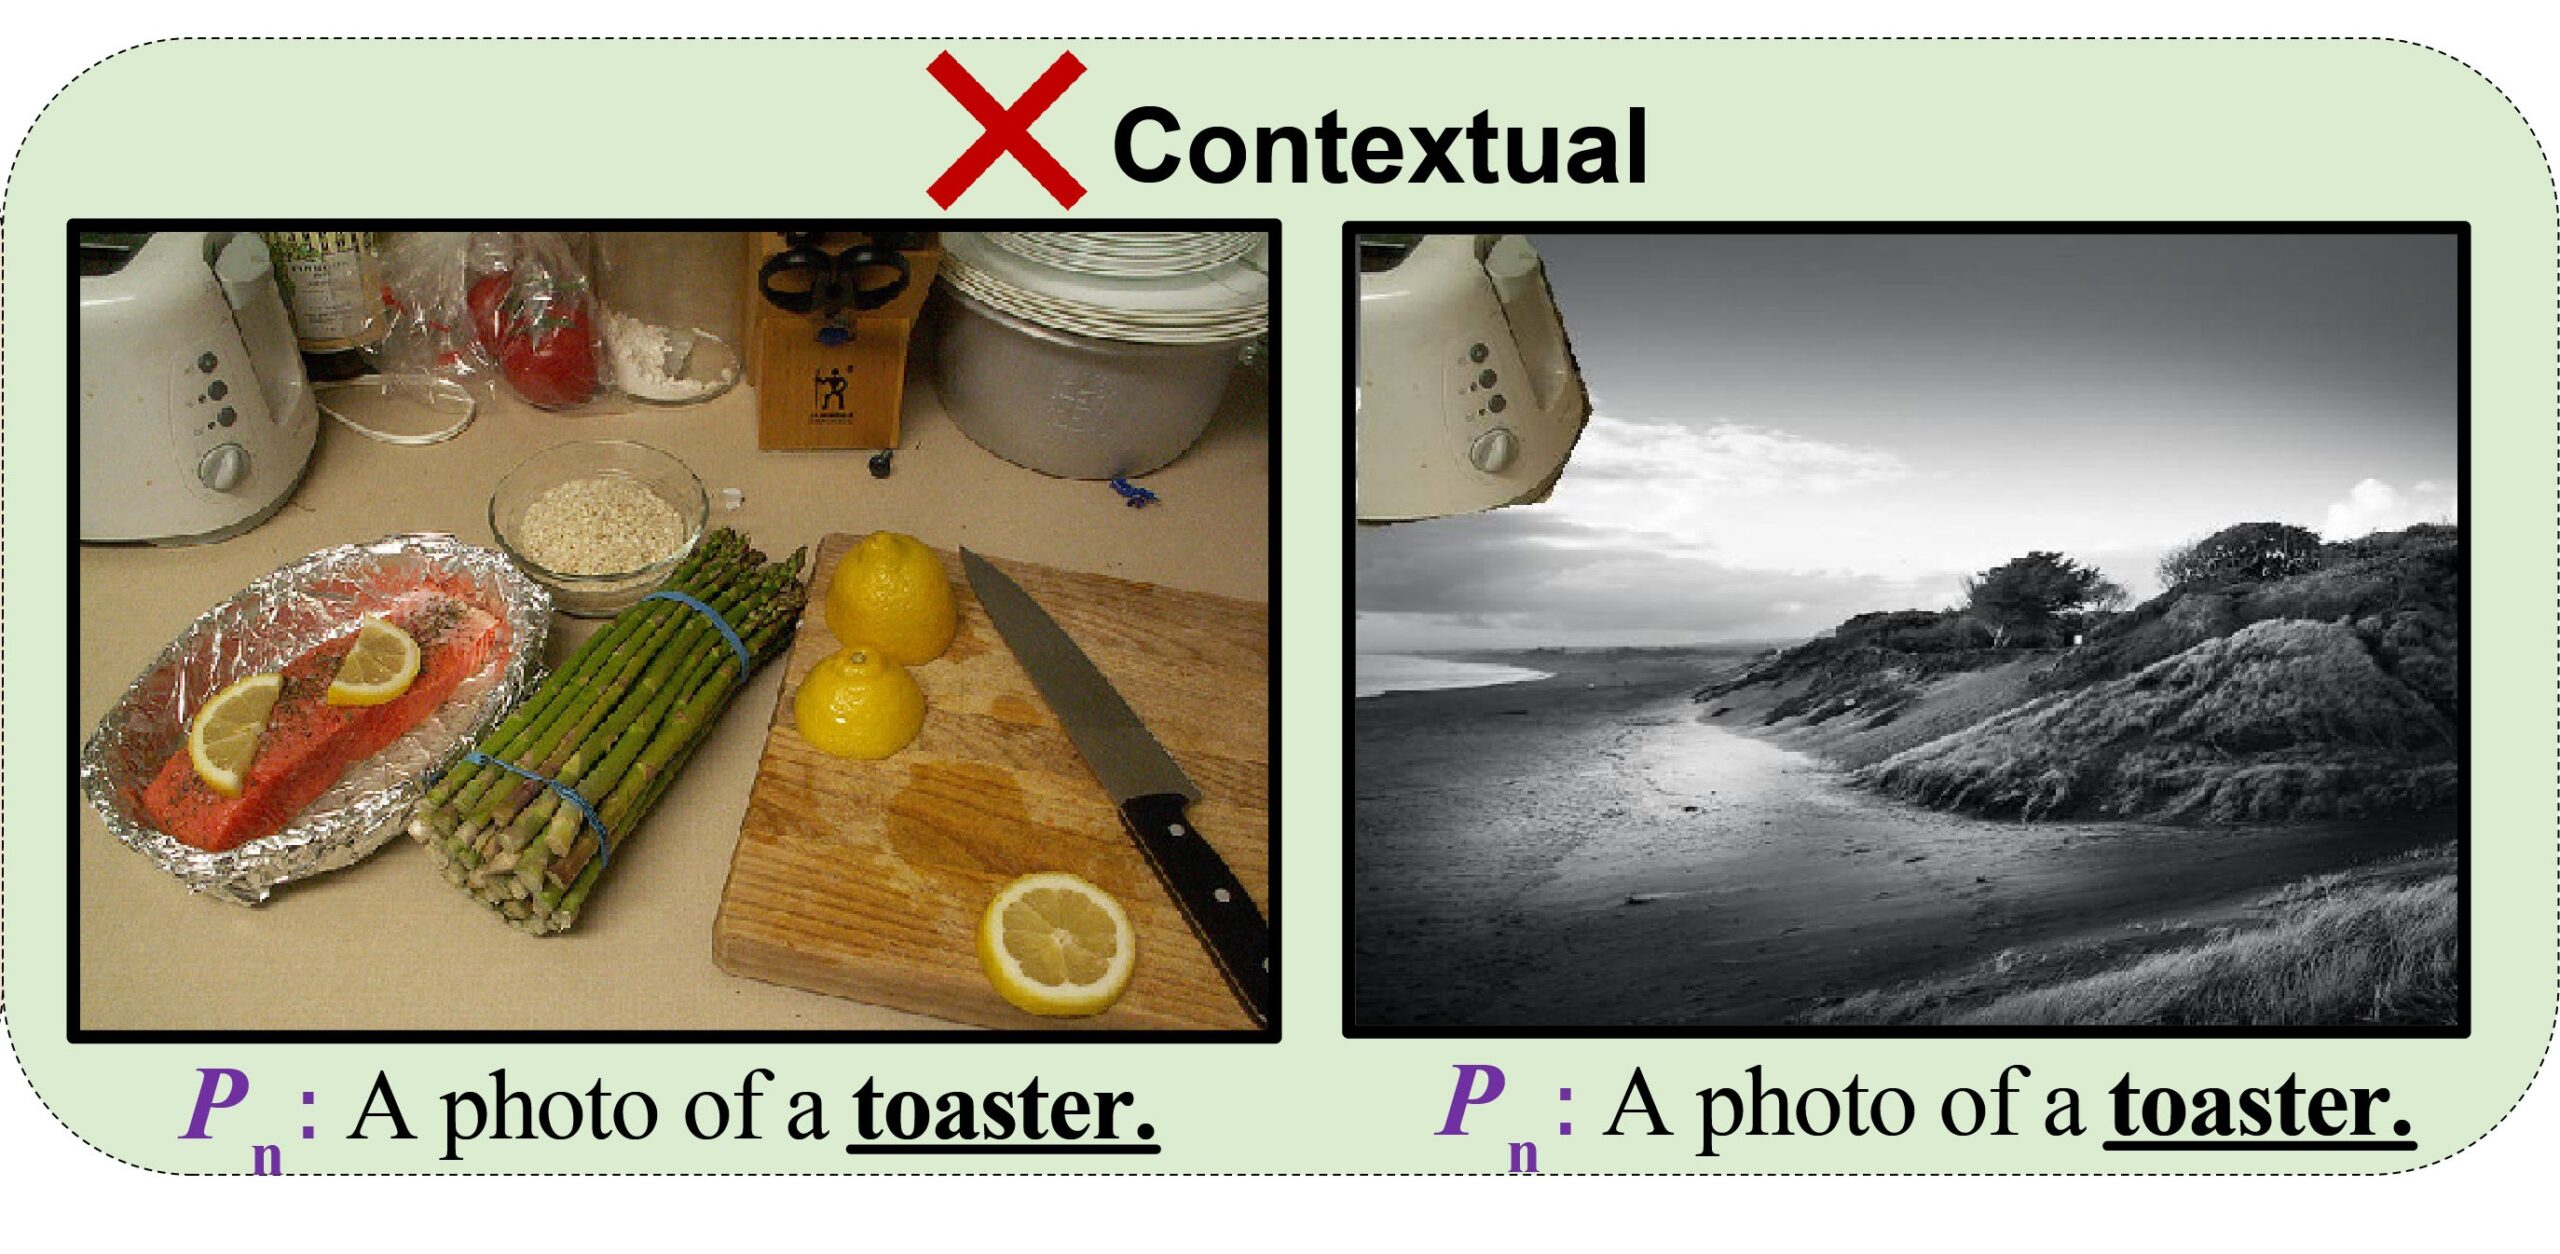
| Dataset | # Images | # Objects | Other |
|---|---|---|---|
| Probe R | 99,960 | 6006 | 2456 Relations |
| Probe C | 99,886 | 2462 | 114 Compositions |
| Probe B | 33,229 | 80 | 4 Fillers |
Probing Conceptual Understanding of Large Visual-Language Models
Madeline Schiappa, Raiyaan Abdullah, Shehreen Azad, Jared Claypoole, Michael Cogswell, Ajay Divakaran, Yogesh Rawat
CVPR Workshop 2024
GeoMeter
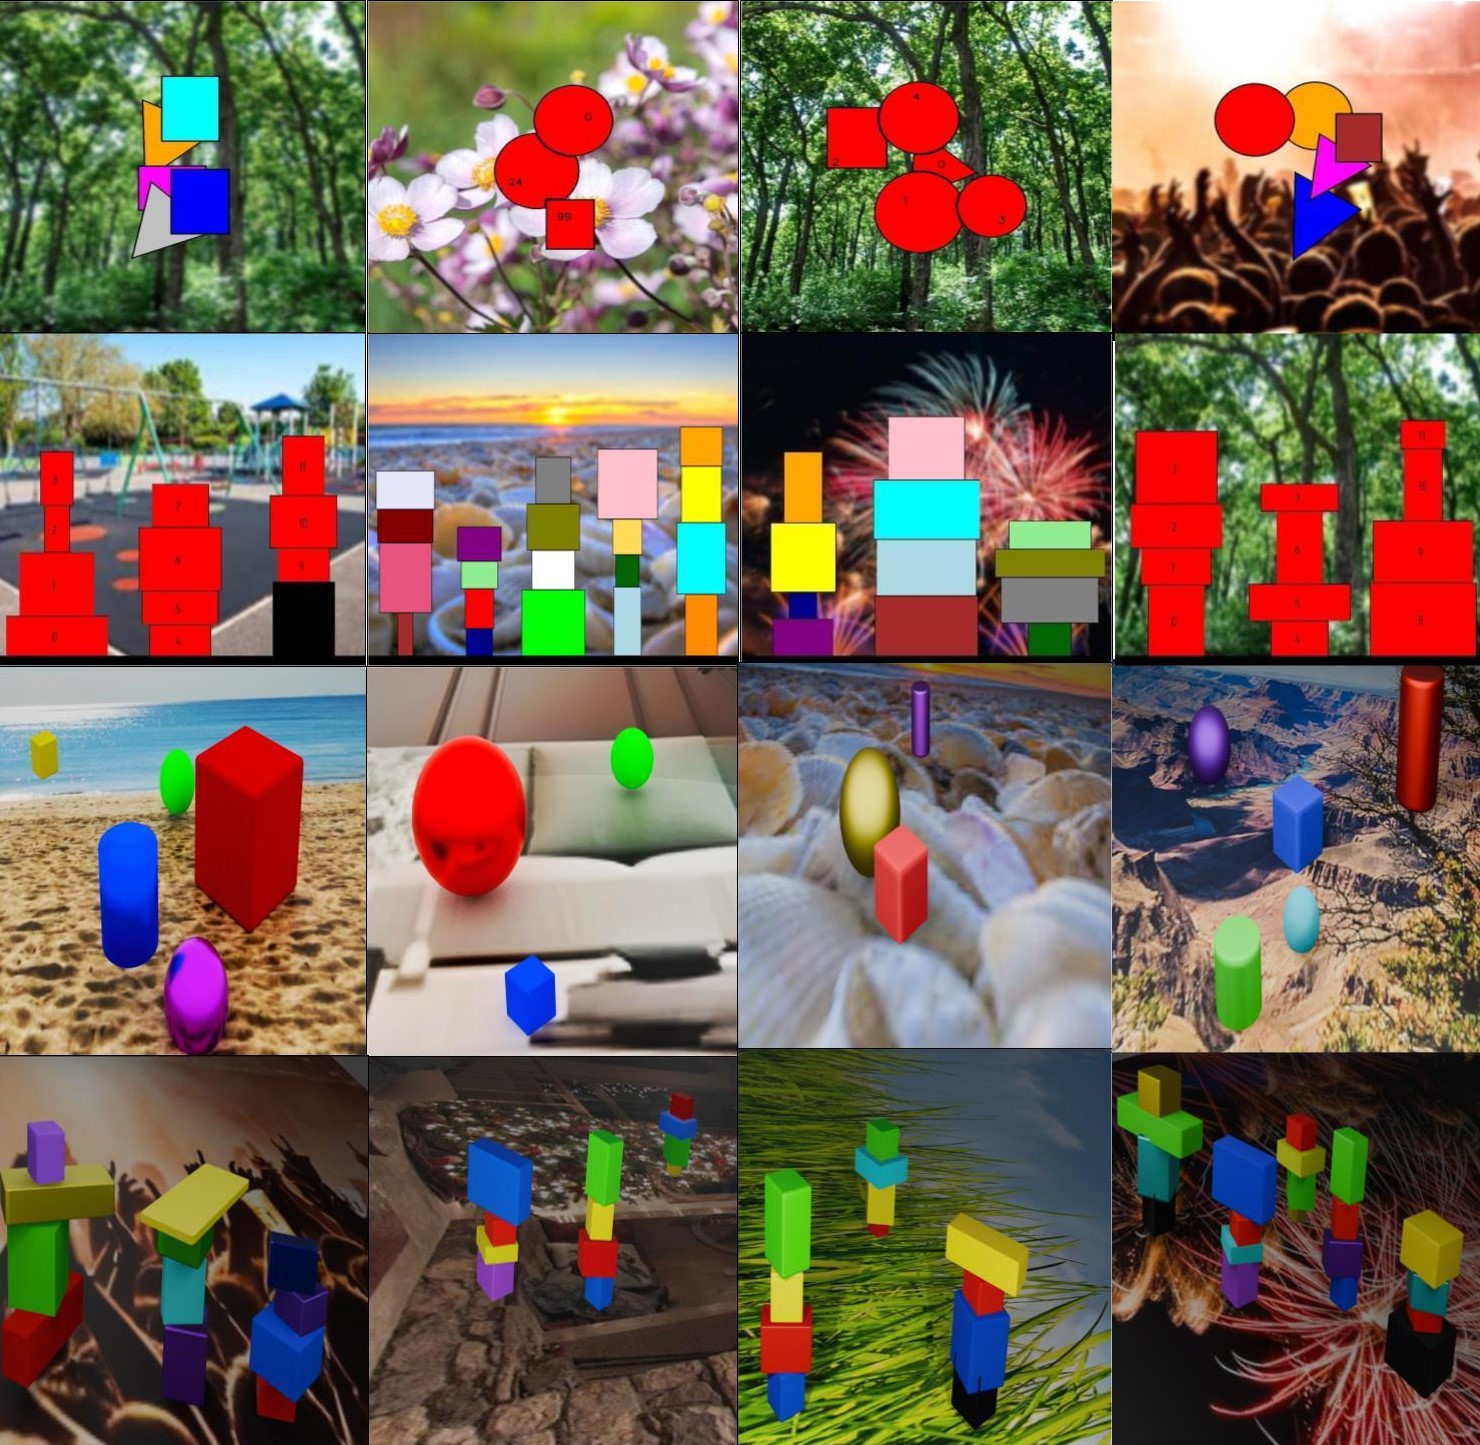
| No. of Image-Text Pairs |
|---|
| 11k |
GeoMeter: Probing Depth and Height Perception of Large Visual-Language Models
Shehreen Azad, Yash Jain, Rishit Garg, Yogesh S Rawat, Vibhav Vineet
Action Recognition
NoisyActions2M
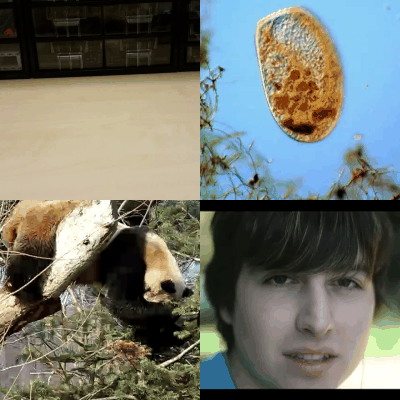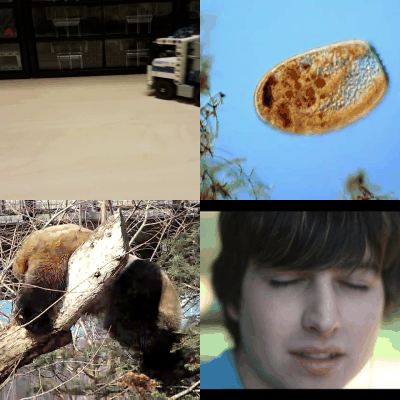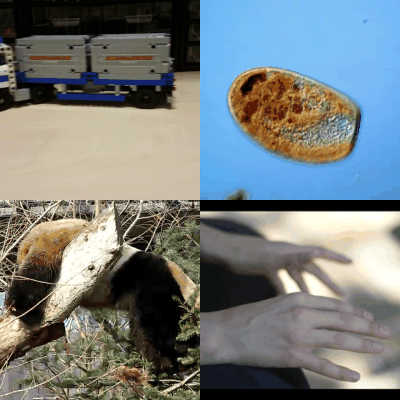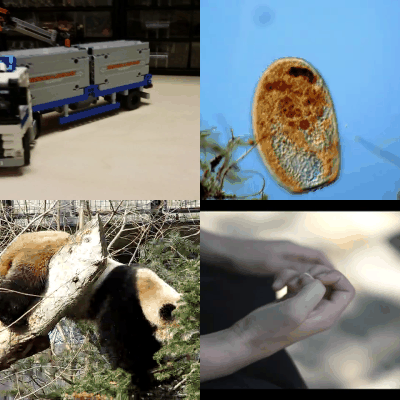
| No. of Videos | No. of Classes | Label Type | Avf. Duration |
|---|---|---|---|
| 2M | 7000 | Multi-Label | 123s |
NoisyActions2M: A Multimedia Dataset for Video Understanding from Noisy Labels
Mohit Sharma, Raj Patra, Harshal Desai, Shruti Vyas, Yogesh Rawat, Rajiv Ratn Shah
ACM MM Asia 2021
Segmentation
MS COCO-P
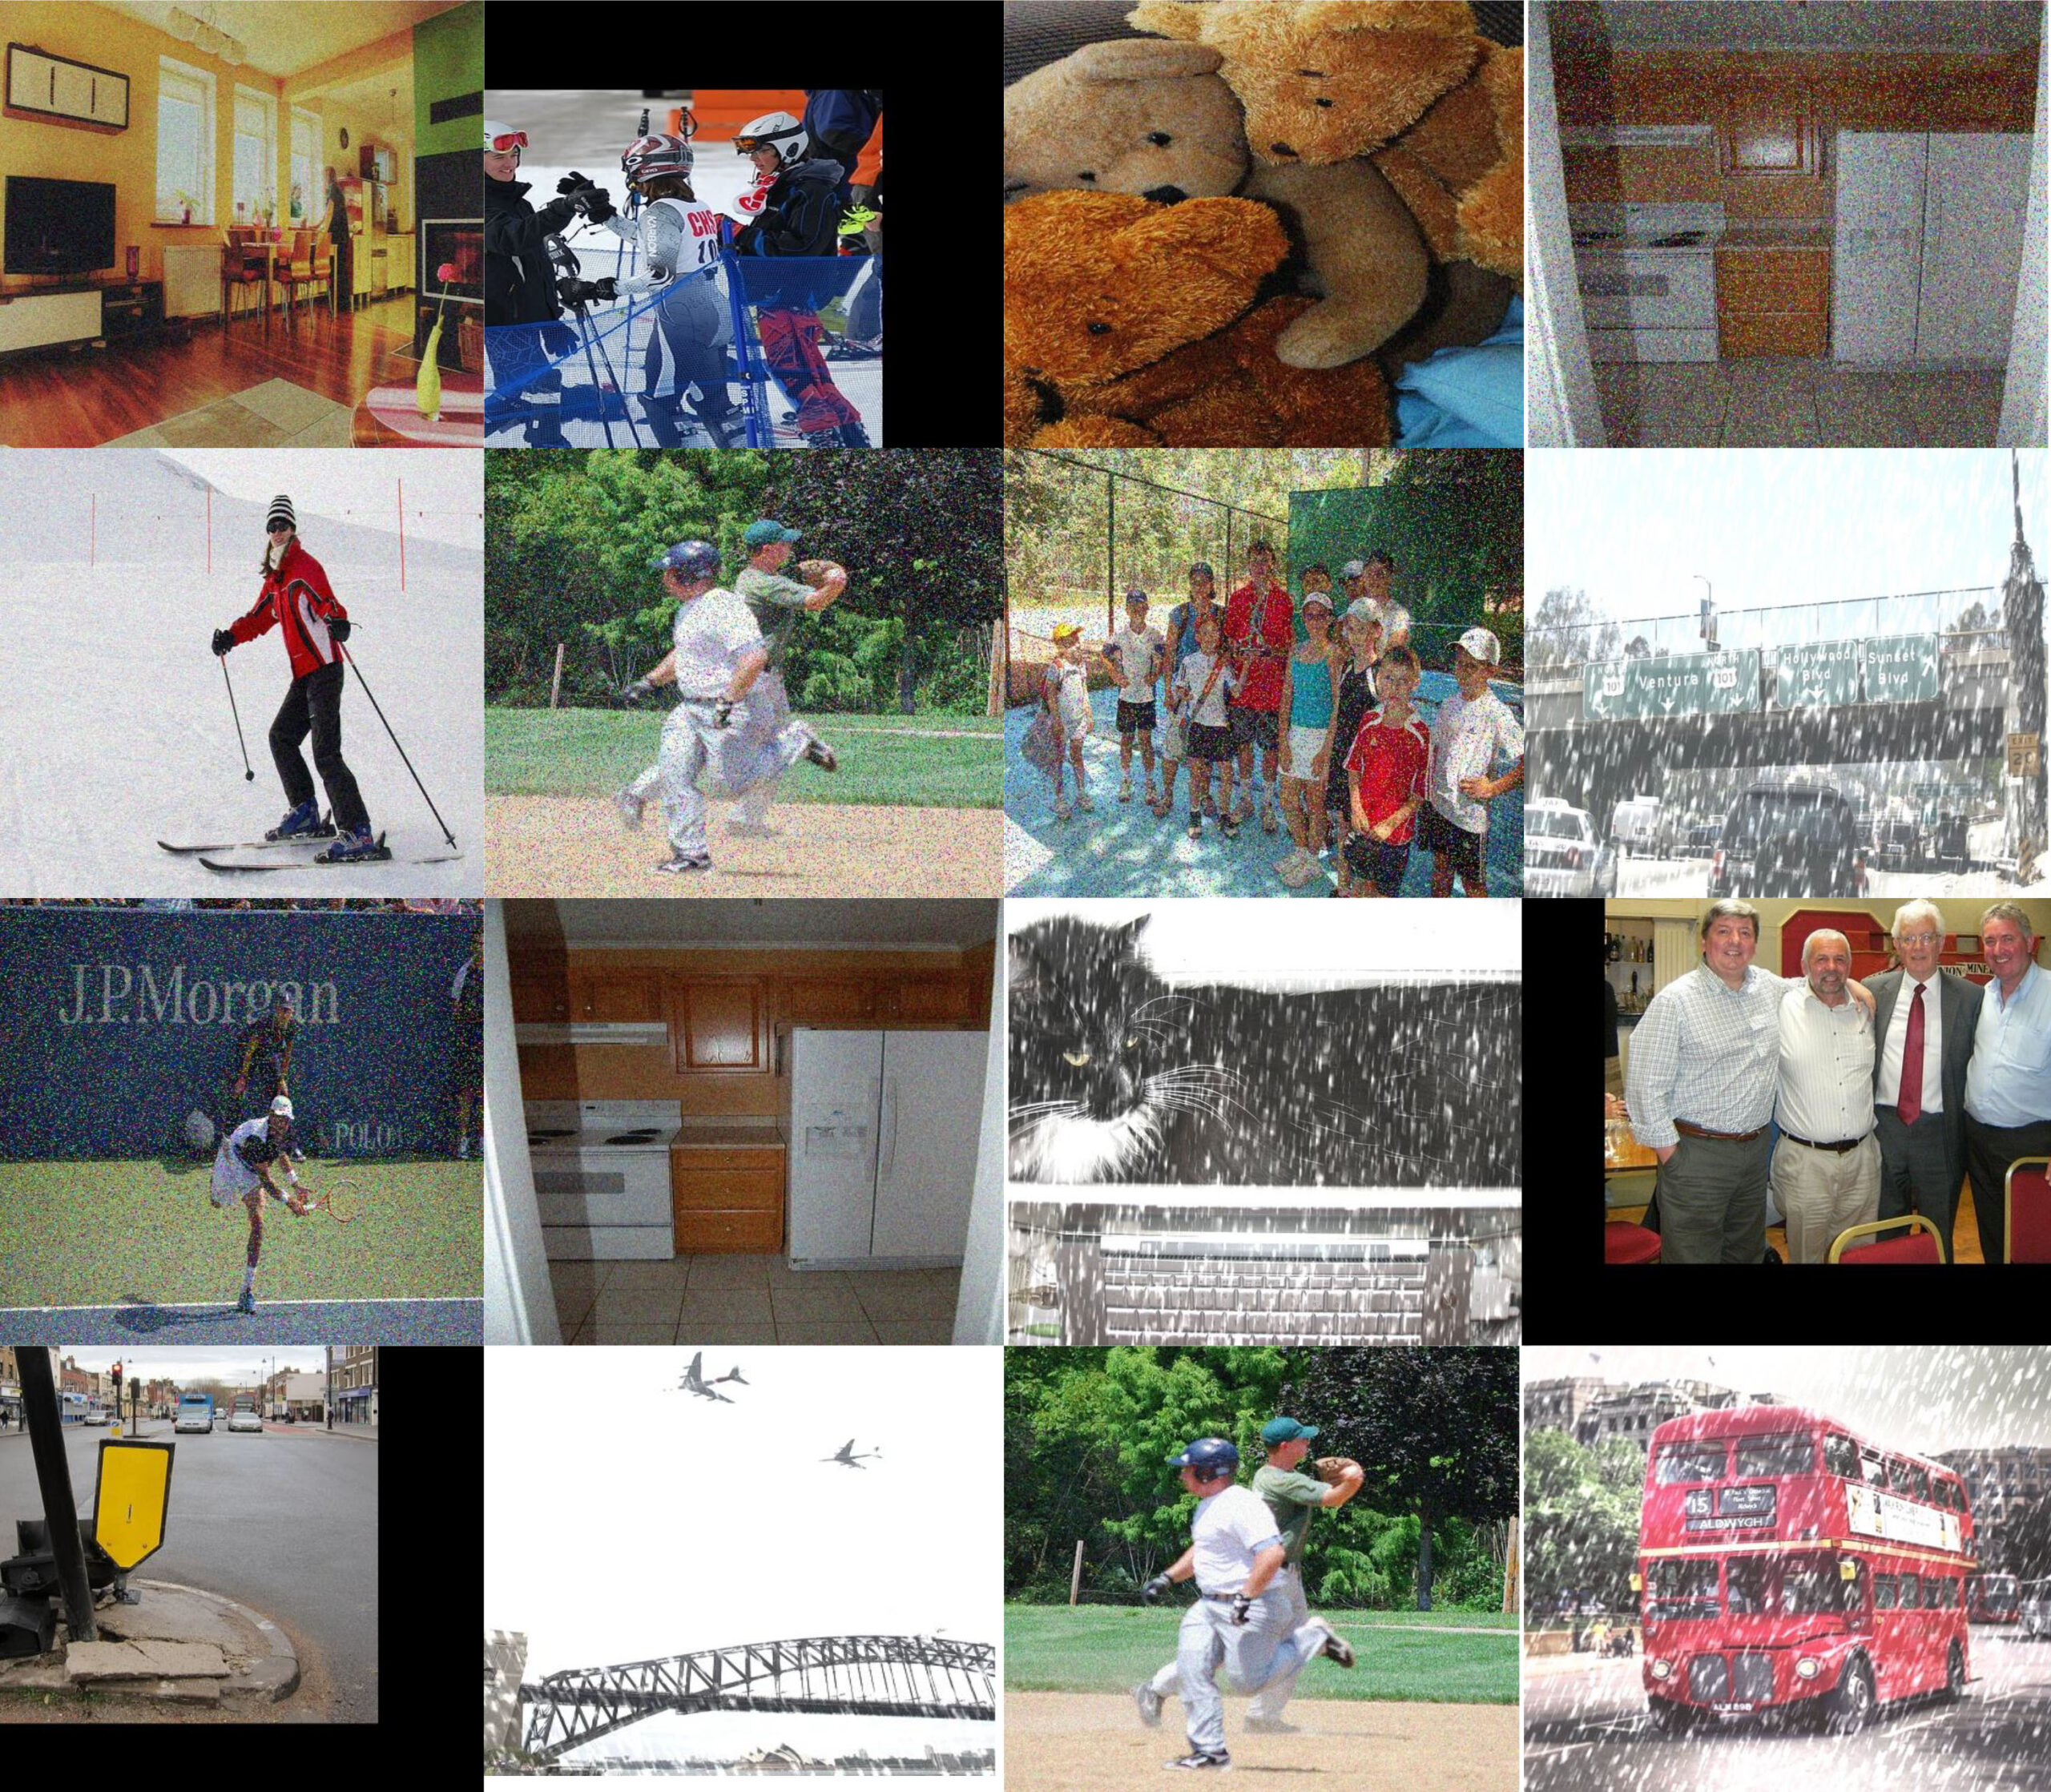
| Things Categories | Stuff Categories | Total Images |
|---|---|---|
| 80 | 53 | 425,000 |
Robustness Analysis on Foundational Segmentation Models
Madeline Chantry Schiappa, Shehreen Azad, Sachidanand VS, Yunhao Ge, Ondrej Miksik, Yogesh S Rawat, and Vibhav Vineet
CVPR Workshop 2024
ADE20K-P
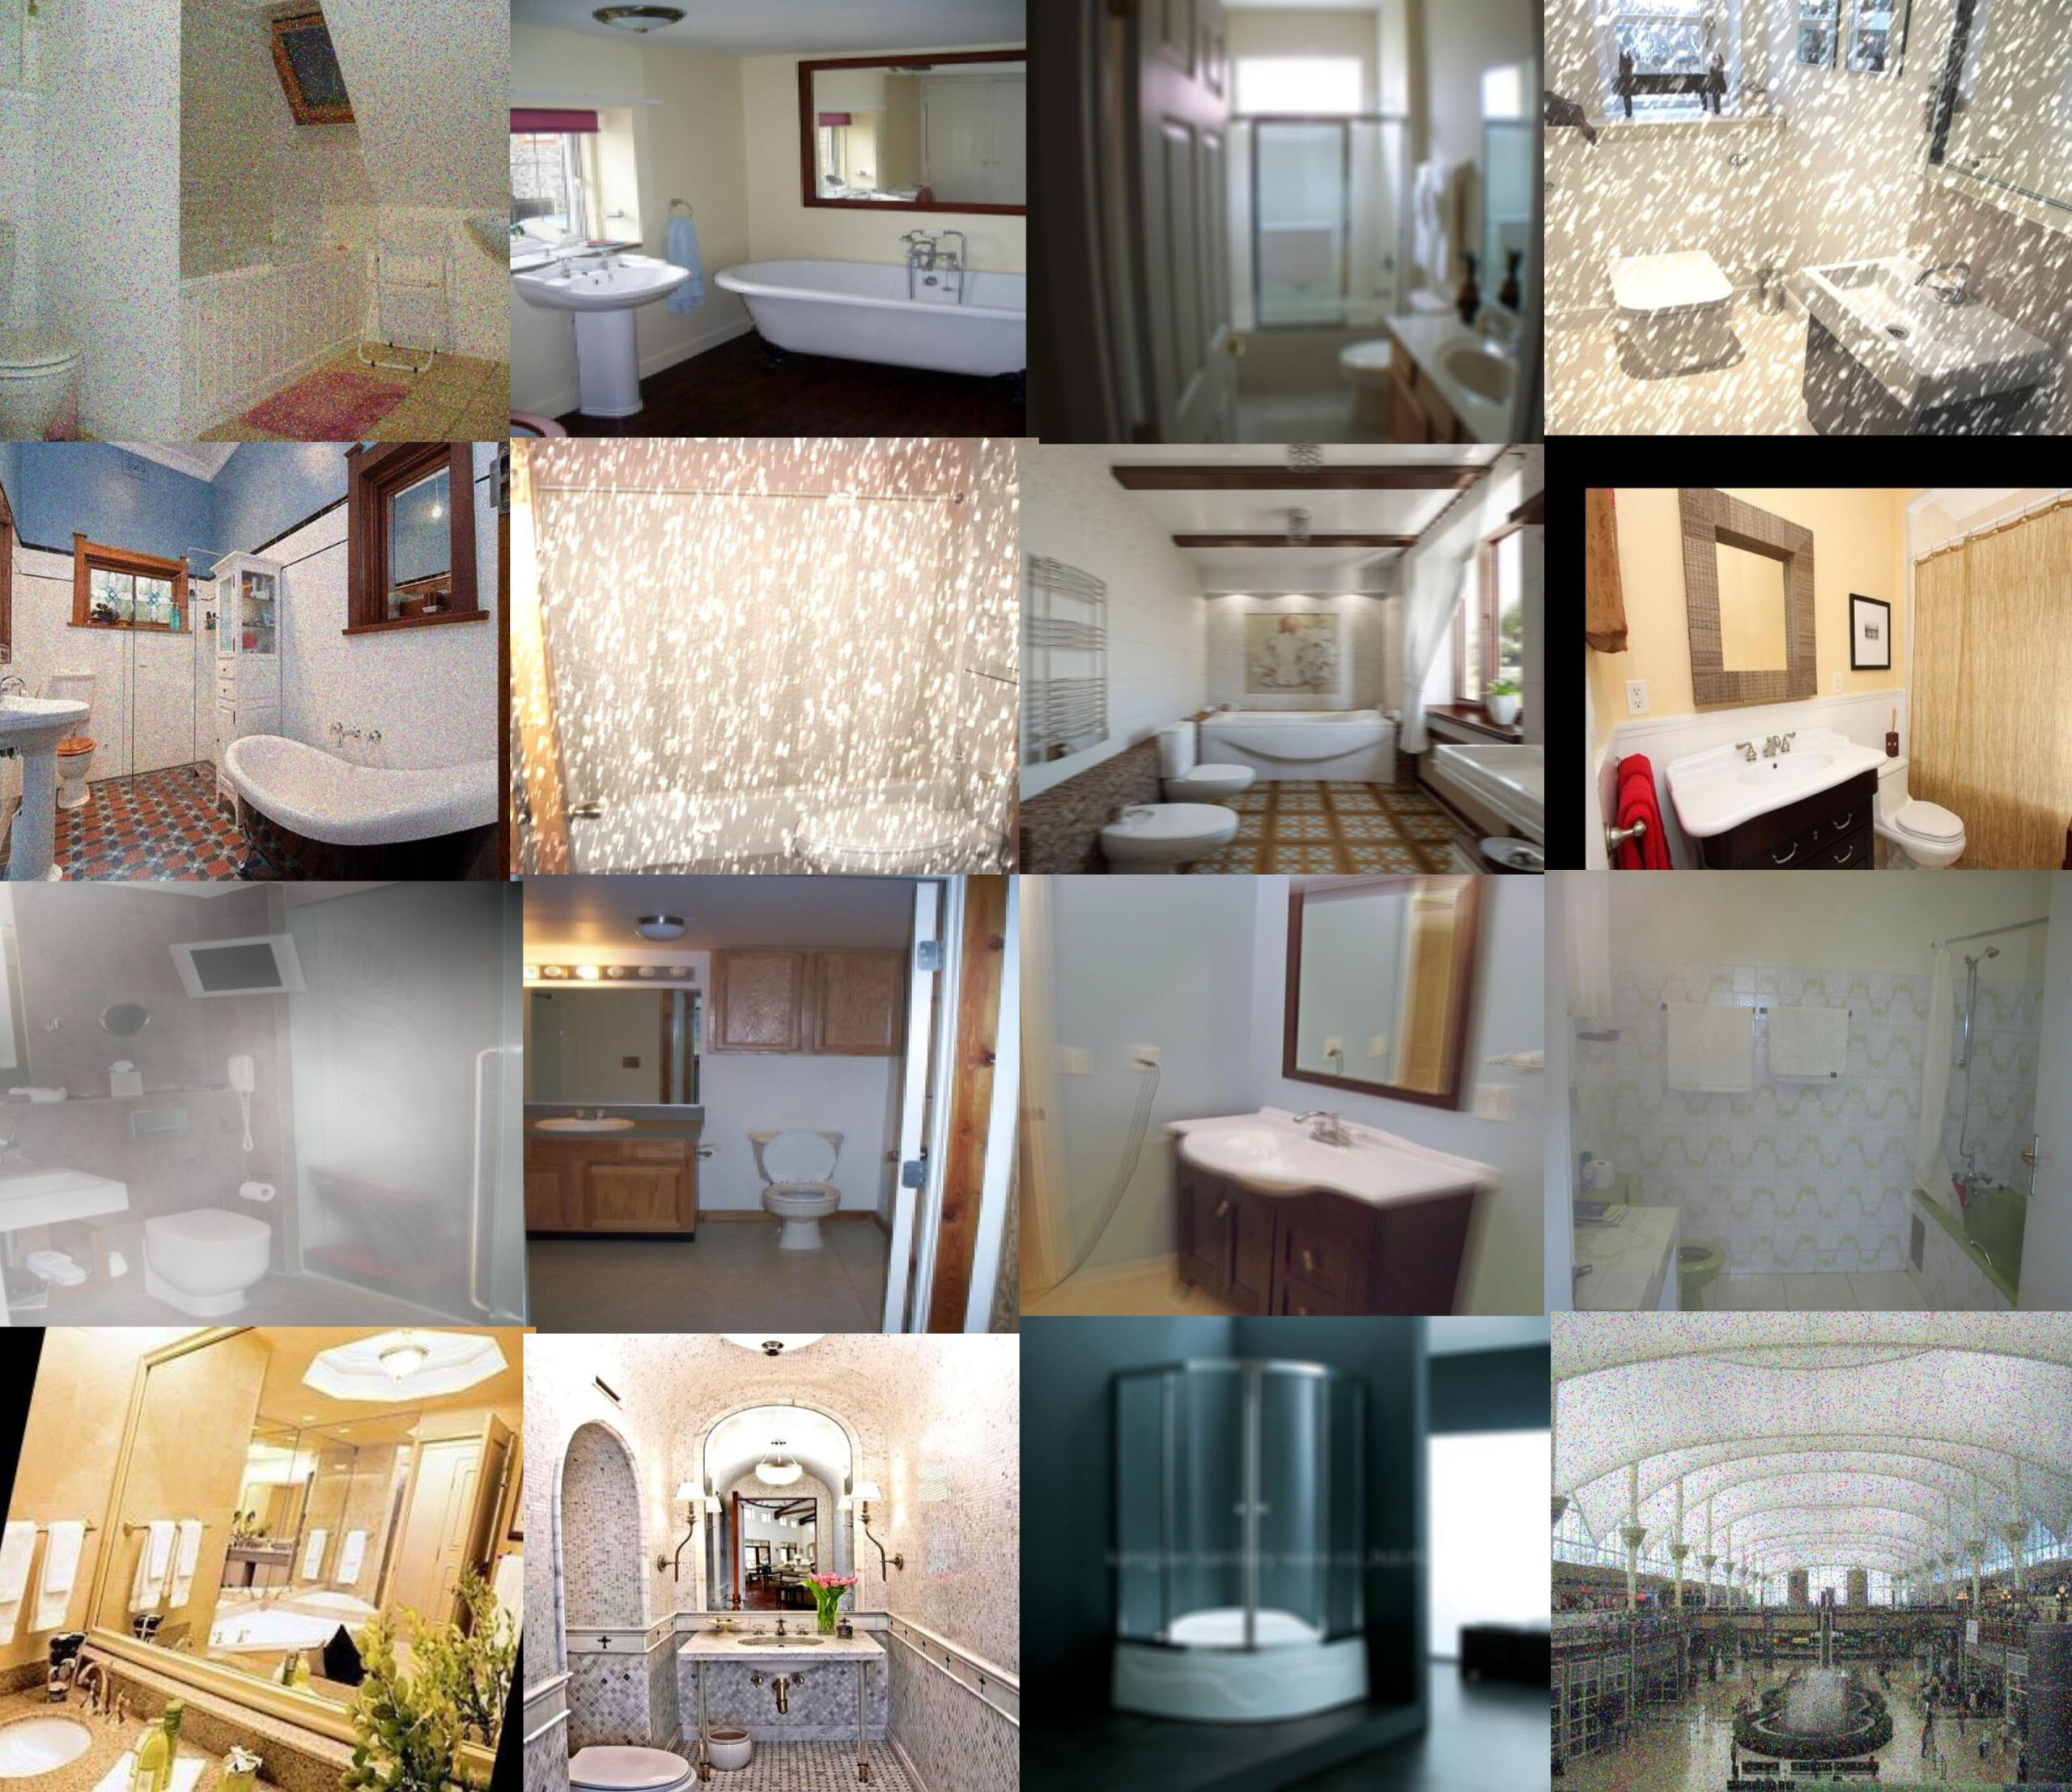
| Things Categories | Stuff Categories | Total Images |
|---|---|---|
| 100 | 50 | 170,000 |
Robustness Analysis on Foundational Segmentation Models
Madeline Chantry Schiappa, Shehreen Azad, Sachidanand VS, Yunhao Ge, Ondrej Miksik, Yogesh S Rawat, and Vibhav Vineet
CVPR Workshop 2024